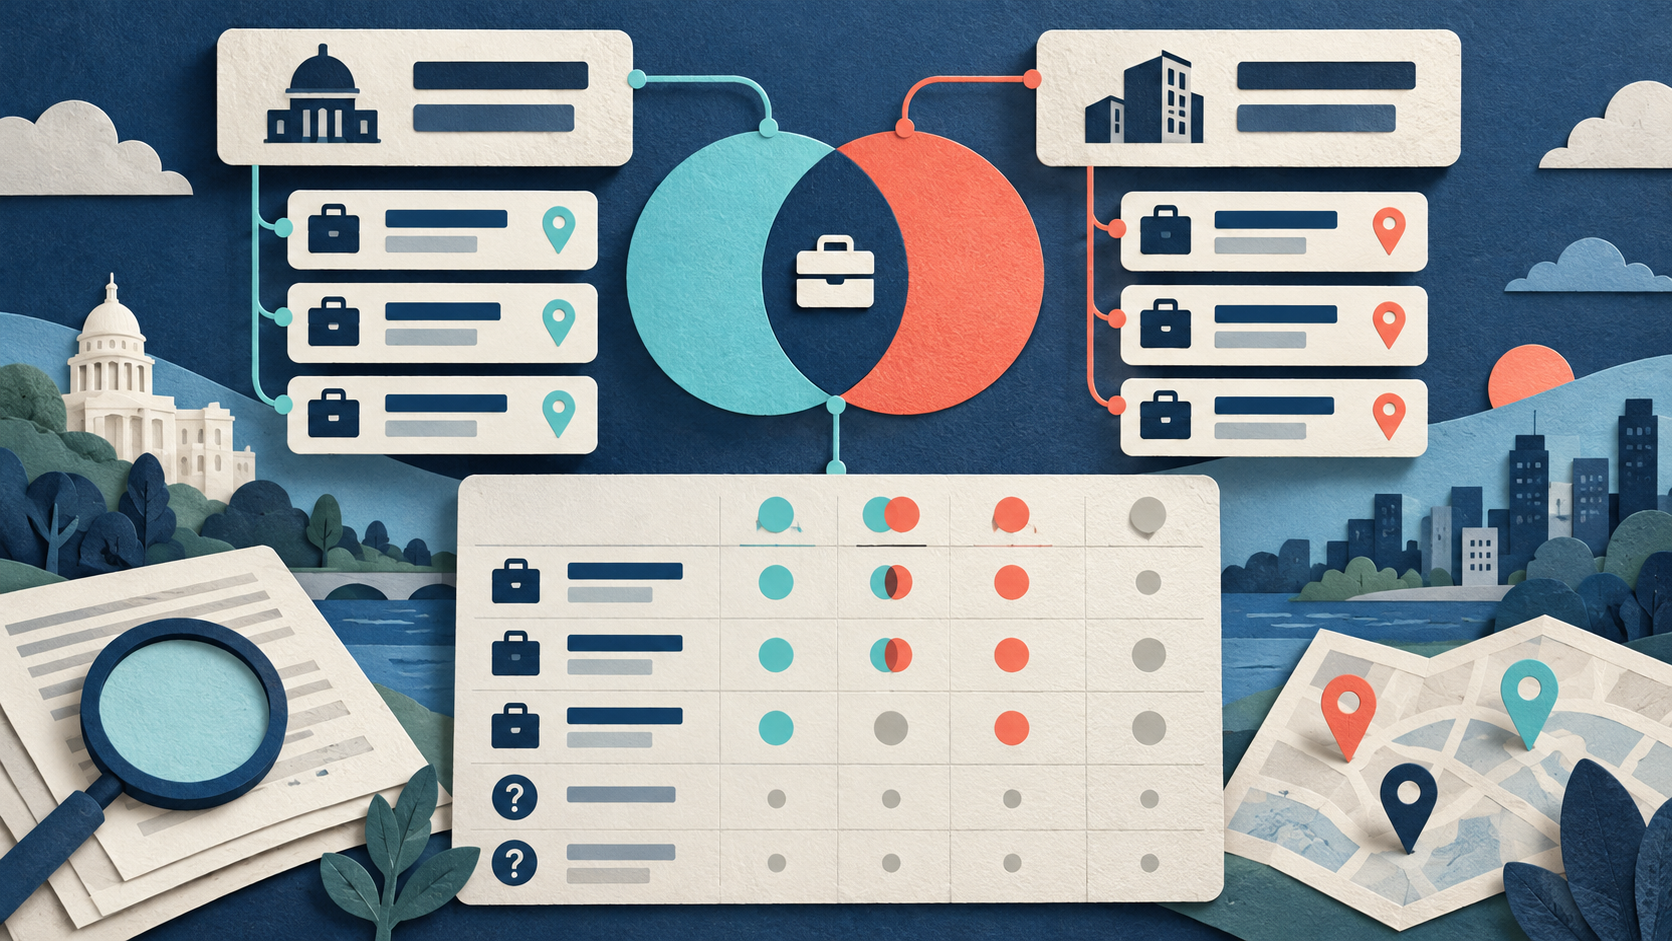
An automated collector on the web is called an Actor. A saved set of settings for an Actor is called a Task. When a job scraper exports only 5 jobs even though a web page shows 50 or more, people often guess that pagination caused the missing rows. Pagination is how a website splits a long list across multiple pages. Guessing is unsafe because filters, row limits, or blocked pages can cause the exact same outcome. You must test each cause with clear evidence before changing your settings.
+-----------------------------------------------------------------------+
|                       Check Output Summary                            |
+-----------------------------------------------------------------------+
                                   |
         +-------------------------+-------------------------+
         |                                                   |
         v                                                   v
[stopReason matches reported cap]                   [failedRequests > 0]
         |                                                   |
         v                                                   v
Row cap or page limit hit based                      Request failures recorded;
on actual stored stop evidence. cause remains unresolved.The public LinkedIn Jobs Scraper and its preset Task example define the collection rules. The current saved input has `searchTerm` set to software engineer, `maxItems` set to 100, `maxPagesPerSearch` set to 2, `postedWithin` set to 7d, `saveOnlyUniqueItems` set to true, and `fetchJobDetails` set to true. Your pilot test replaces the query, sets `maxItems` to 3, and sets `maxPagesPerSearch` to 1. Different input modes share one single row cap. Retain these exact output fields: `jobId`, `jobUrl`, `title`, `companyName`, `locationRaw`, `descriptionStatus`, and `scrapedAt`. Inspect these exact available output summary keys: `candidateItemsSeen`, `jobsSaved`, `duplicatesSkipped`, `stopReason`, `pagesParsed`, `pageLimitSearches`, `blockedRequests`, `failedRequests`, `detailRequests`, `detailPagesParsed`, `detailFailures`, plus separate filter counters `rowsExcludedByCompany`, `rowsExcludedByDate`, `rowsExcludedByJobType`, `rowsExcludedByWorkplace`, `rowsExcludedByExperience`, and `rowsExcludedByTitle`. Use the separate exact stored exclusion counters; each describes its own category. A successful three-row control run proves only that a positive input works; it does not prove the cause of an empty target query.
How to Diagnose a Reduced Result Count
Follow these steps to find out why your job count is lower than expected.
- Save the exact input settings, run time, summary output, and a small row sample before changing anything. Confirm whether your expected count comes from the exact same job title, country, date range, sort order, and user account.
- Validate your input mode. Keyword searches, direct search web links, and specific job identification numbers work differently. If you mix these modes, they still share one total row cap. A leftover search word can widen or change your search without your knowledge.
- Check restrictive filters and units. A distance radius needs a location. A last-day filter can narrow candidate scope compared with last-week, not guaranteed fewer saved rows, especially with caps. Compare same input/source scope and inspect actual evidence. Title and company exclusions can remove candidates. Change one justified input at a time and save old evidence.
- Check `jobsSaved`, the shared `maxItems` cap, `maxPagesPerSearch`, and `stopReason`. Saved rows equal to your active cap do not automatically prove a row cap caused the stop unless actual stored stop evidence states so. A page limit can stop discovery before all visible pages. Do not assert either caused the gap unless the actual summary stop reason supports it.
- Inspect candidate counts, skipped duplicates, and filter counts. The total found items key is `candidateItemsSeen`. The skipped duplicate key is `duplicatesSkipped`. You may see 20 candidate listings but save only 5 unique rows because repeated or filtered listings are ignored. Make sure your summary numbers add up using the exact definition of each field.
- Inspect source access errors and detail page results separately. A search can find job titles even when full text descriptions fail to load. The key for full text status is `descriptionStatus`. Missing text descriptions do not mean the job listing count was zero. A failed web request is an error, not a successful search with zero jobs.
- Run a small known-positive control with the same build to test basic collection. A successful known-positive control supports only that the control worked; the target search remains uncertain unless actual scope and source evidence settles it. If the control fails too, keep a source and runtime hold and contact support with safe input and summary evidence.
- Run only one targeted test based on your findings. Do not continually raise limits or rerun a blocked scraper. Your final result should be a diagnostic table that points to one clear next step.
Diagnostic Decision Table
Use actual stored stop and page evidence with reader descriptions to diagnose your run.
| Saved Count vs Cap | Stop Reason Evidence | Request Failures | Filter Activity | Diagnosis |
|---|---|---|---|---|
| `jobsSaved` matches active cap | Stored stop reason reports cap reached | 0 | 0 | Collection stopped because it hit the row limit, supported by actual stop evidence. |
| `jobsSaved` is below active cap | Stored stop reason reports page limit reached | 0 | 0 | Collection stopped because it hit the page boundary, supported by actual stop evidence. |
| `jobsSaved` is below active cap | Stored stop reason reports normal exhaustion | 0 | Active filter counters present | Filter rules removed matching candidate rows during normal input exhaustion. |
| 0 | Stored stop reason reports request or block issues | Greater than 0 | 0 | Request failures recorded; cause unresolved. |
Fictional Worked Examples
Four invented runs, each with its own input and summary:
- A: `maxItems` 3, `jobsSaved` 3, with an explicit reported cap stop reason. Diagnosis: shared save cap reached based on explicit stop evidence; no inference about total market jobs.
- B: `maxItems` 20, `maxPagesPerSearch` 1, `jobsSaved` 5, with an explicit reported page stop reason. Diagnosis: page boundary explains that run's collection stop based on explicit stop evidence; try one extra page if the source permits, not unlimited pagination.
- C: `candidateItemsSeen` 10, `duplicatesSkipped` 3, `rowsExcludedByTitle` 2, `jobsSaved` 5, with normal input exhaustion reported in reader descriptions. Under these fictional disjoint candidate meanings, 10 minus 3 minus 2 equals 5. Diagnosis: unique and filter policy explains the saved count. Note that 3 out of 5 saved jobs have full text readiness while 2 are missing; this detail state does not change the 5 listing count.
- D: `jobsSaved` 0, 1 failed request, 1 blocked request. Diagnosis: request failures are established, but the cause between network issues versus access blocking is unresolved. There is no proved market zero.
Diagnostic Ledger
Record your run metrics in a ledger like this to compare settings and select your next check.
| Run | Active Scope | Active Cap | Page State | Candidate / Filter Evidence | Source State | Diagnosis and Next Check |
|---|---|---|---|---|---|---|
| A | Software Engineer, US | 3 | Page 1 of 2 | 3 seen / 0 filtered | Healthy | Explicit cap stop. Raise `maxItems` if justified. |
| B | Software Engineer, US | 20 | Page 1 of 1 | 5 seen / 0 filtered | Healthy | Explicit page stop. Increase `maxPagesPerSearch` to 2 if permitted. |
| C | Software Engineer, US | 100 | Page 2 of 2 | 10 seen / 3 duplicates, 2 title exclusions | Healthy | Normal input exhaustion. Review title exclusion settings. |
| D | Software Engineer, US | 100 | Page 0 of 2 | 0 seen / 0 filtered | 1 failed, 1 blocked | Source uncertain beyond reported failures. Hold run and report log evidence. |
Sources & further reading
By Chronometrica · Updated
Back to top ↑