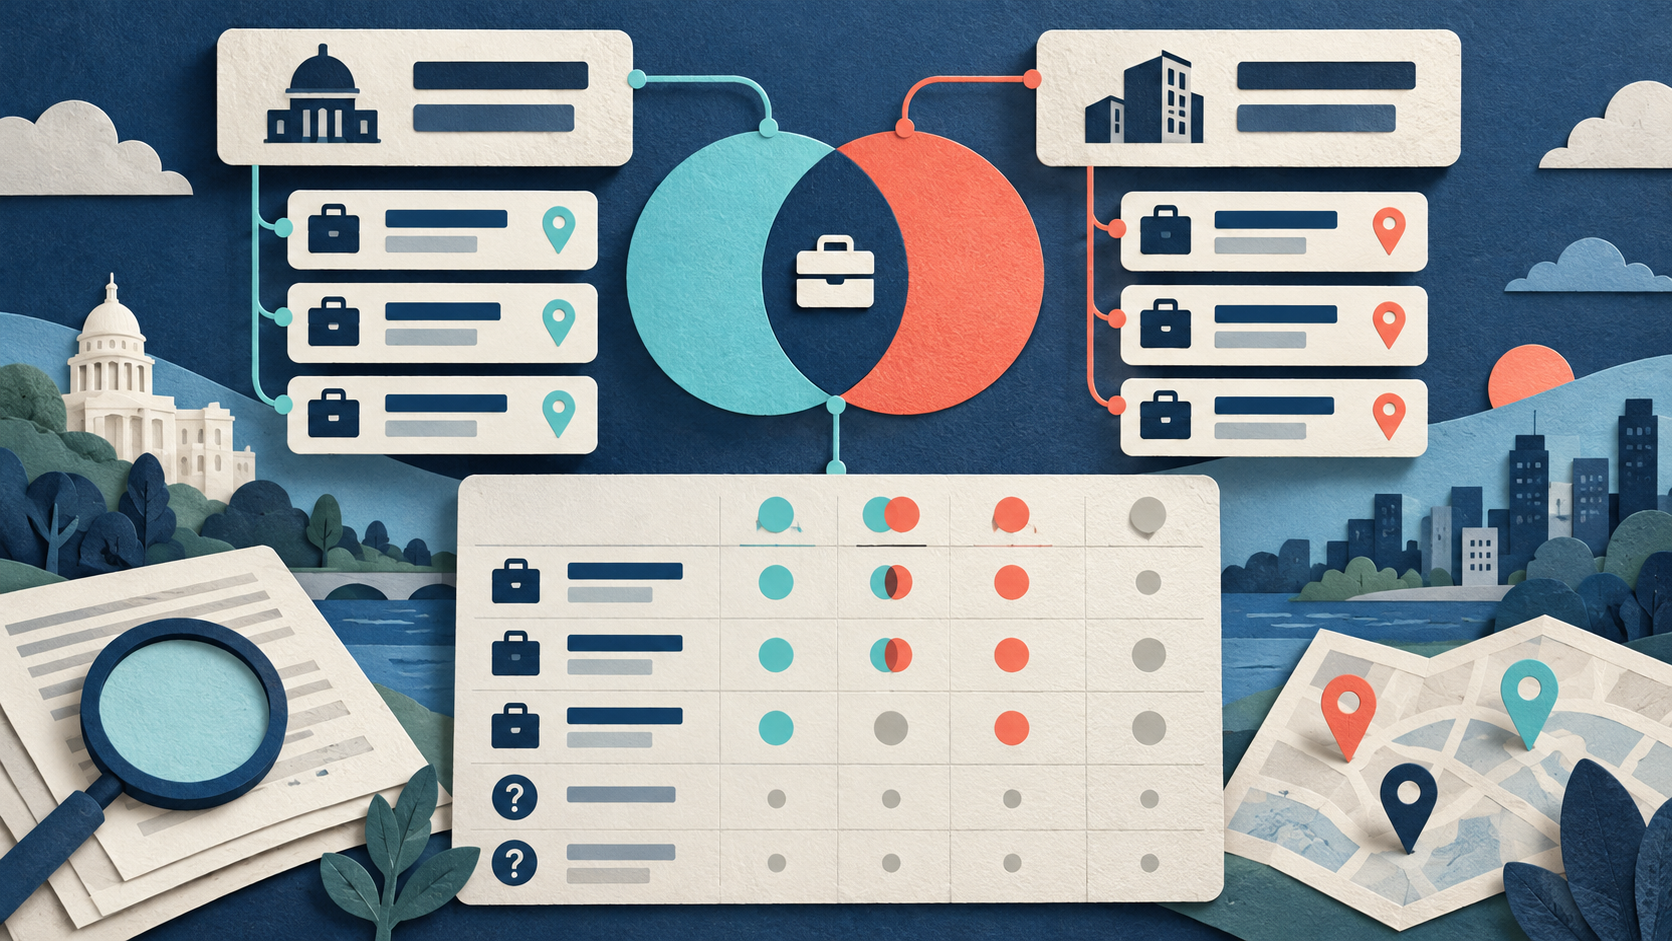
Core Distinctions and Definitions
A listing is one board posting published on a specific job board. A vacancy is an underlying employer opening in the real world. An observation is a single data reading captured at collection time. An exact copy is the exact same observation imported twice into your file.
A source key combines the platform source and the listing ID, such as `linkedin:L101`. Keep job IDs strictly as text. An employer reference is an employer-supplied job code publicly visible in the job description or employer page when available. Employers can reuse these public codes. A review group holds possible matches with recorded reasons. Groups are possible matches, not confirmed openings.
An Actor is a hosted data collection program.
Job boards treat postings in different ways. LinkedIn treats a reposted closed, expired, or changed job as a new posting instance, as described in the LinkedIn reposting guide. This policy does not prove universal ID changes or employer hiring intent. Indeed separates duplicate postings from reopened roles, as outlined in the Indeed posting integrity rules. These rules do not prove that collected repeated listings are improper. Google structured data rules define employer job identifiers and allow multiple locations, as detailed in the Google job posting documentation. The checked Actor contract, rather than Google rules, defines how `jobId` identifies board postings.
Job analysts use these rules when combining exports. Readers ask whether repeatedly reposted roles on LinkedIn are real openings, as seen in a LinkedIn job reposting query. External research tracks raw, unique, and repeated postings, as shown in an Indeed dataset analysis. Those totals are unverified external context. Public scrapers capture raw records into datasets, as explained in the Apify dataset guide. Analysts use these tools to collect rows, remove exact duplicates, and group possible reposts.
Task Setup and Collection Setup
A Task is a saved starting configuration for an Actor. A Task collects data. It does not classify reposts or schedule runs. The Export LinkedIn Jobs to CSV or Excel Task uses the LinkedIn Actor. The default configuration requests 25 jobs. The Indeed Reposted Job Evidence Dataset Task uses the Indeed Actor. Its preset requests 500 jobs across 15 pages. Both tools collect public data without user login cookies.
Adjust settings before collecting a test sample. Set your search query. Set `maxItems` to 3. Set `maxPagesPerSearch` to 1. Keep `saveOnlyUniqueItems` set to true. Set `fetchJobDetails` to true on LinkedIn to collect full descriptions. Check `descriptionStatus` on returned records. Snippets cannot establish full text matches.
The `saveOnlyUniqueItems` setting removes repeated listings within a single run. It does not group listings across runs or match vacancies. The `maxItems` setting acts as a shared saved-row cap. Review the OUTPUT summary after a run. Check `jobsSaved`, `duplicatesSkipped`, `candidateItemsSeen`, and `stopReason`. Subtracting saved jobs from candidate items does not automatically equal duplicate counts.
The scraper returns `scrapedAt` as the collection timestamp. It returns `postedAtRaw` as the original source date text or relative age label. It returns `postedAt` by parsing exact source dates or deriving a timestamp from relative text like "6 days ago". Preserve source precision and keep both fields. A derived value is not an exact publication time. Reviewers derive `firstSeen` and `lastSeen` values from successful retained observations, not from built-in recovered history. Collection gaps do not prove job closure, reopening, or a filled role.
10-Step Method for Analysts
- Retain raw exports. Save an unchanged source export before editing data. Add import file names and row numbers in your working copy so you can find original source records.
- Form the listing key. Combine the source name and the text job ID, such as `linkedin:L101`. Keep IDs as text. Do not join bare IDs across boards or merge blank IDs.
- Find copied observations. Find exact copies by comparing source key, `scrapedAt`, and all retained source values. Exclude import file names, row numbers, and review notes from equality checks. Different source values must stay as separate rows for review.
- Retain later readings. Keep later observations of the same listing. Preserve changed duties, titles, locations, and status fields across runs. Do not merge fields from different collection times into one combined row.
- Set missing IDs aside. Move records without job IDs into a separate review table. Checked source URLs may offer identity clues. Titles, company names, cities, and blank fields cannot establish an automatic match.
- Create review pairs. Compare listings only within the same checked employer. Compare titles, locations, full duties, and collection times. Trim spaces in comparison columns, but preserve raw source text. Keep team names, seniority levels, locations, and employer references. Shared standard employment text does not prove listing identity. Do not make automatic matching claims.
- Compare listing details. Compare full duties, employer references, teams, seniority, work types, and locations. The same employer, title, and city can belong to separate openings. Different employer references or different duties support separate openings. Matching employer references help review, but employers can reuse codes.
- Record review choices. Label pairs as `same_listing`, `possible_same_vacancy`, `separate_listing`, or `unresolved`. Record evidence, reasons, reviewer name, and review date. A `possible_repost` classification requires a later listing ID and matching duties. Simultaneous postings on different boards are cross-source candidates, not automatic reposts.
- Compare group members directly. Compare every added member against the primary group reference. If listing A matches listing B, and listing B matches listing C, listing A does not automatically match listing C. Keep conflicting listings separate.
- Count records separately. Count raw rows, distinct observations, source listing keys, and possible review groups as separate numbers. No fixed age window or similarity score proves a match.
Worked Fictional Example: Northshore Tools
All example rows belong to employer Northshore Tools, title Data Engineer, and location Toronto. All IDs are fictional labels. Employer references are reviewer notes, not native Actor fields. The table shows six raw observations from import files.
| Import Row | Source Key | Scraped At | Retained Full Duties Text |
|---|---|---|---|
| R1 | `linkedin:L101` | 2026-10-01T09:00:00Z | Reporting team, batch warehouse duties |
| R2 | `linkedin:L101` | 2026-10-01T09:00:00Z | Reporting team, batch warehouse duties |
| R3 | `linkedin:L101` | 2026-10-03T09:00:00Z | Reporting team, batch warehouse duties |
| R4 | `linkedin:L202` | 2026-10-05T09:00:00Z | Reporting team, batch warehouse duties |
| R5 | `linkedin:L303` | 2026-10-05T09:00:00Z | Product team, low-latency data duties |
| R6 | `indeed:I90` | 2026-10-05T09:00:00Z | Reporting team, batch warehouse duties |
All underlying retained source values in row R2 match row R1, including the full collection timestamp `2026-10-01T09:00:00Z`. Import row labels are outside source value equality. Row R2 is an exact copy.
Row R3 shares the source key `linkedin:L101` and contains the same source values collected at a later time `2026-10-03T09:00:00Z`. It is the same listing read later. Retain row R3 alongside row R1.
Grouping and Counting Steps
- Raw import rows: 6 rows.
- Exact copy removal: Remove row R2 because all source values match row R1.
- Distinct observations: 6 - 1 = 5 valid observations (R1, R3, R4, R5, R6).
- Source listing keys: 4 unique listing keys (`linkedin:L101`, `linkedin:L202`, `linkedin:L303`, `indeed:I90`).
- Possible review groups: 2 groups created. Group G1 contains `linkedin:L101`, `linkedin:L202`, and `indeed:I90` based on matching duties and reviewer note reference NT-20. Group G2 contains `linkedin:L303` based on product team duties and reviewer note reference NT-21.
Provisional Review Group Decision Table
| Review Group | Listing Keys | Review Classification | Reviewer Evidence and Reason |
|---|---|---|---|
| G1 | `linkedin:L101`, `linkedin:L202`, `indeed:I90` | `possible_same_vacancy` | Full duties match. Reviewer noted employer reference NT-20 on descriptions. L202 is a possible repost of L101. I90 is a cross-source candidate. |
| G2 | `linkedin:L303` | `separate_listing` | Duties specify product team and low-latency systems. Reviewer noted employer reference NT-21. Separate listing from G1. |
Confirmed vacancy counts remain unknown. Possible review groups do not confirm underlying opening identity or current availability. Two provisional review groups are not two proven openings.
Actionable Limits and Analytical Boundaries
Leave listings with missing full text marked as unresolved until manual review. When the same ID shows changed duties, retain the new observation in your log. Keep listings separate when titles match but teams or references differ. For different locations, review whether listings represent separate openings or one multi-location post.
If a source URL fails during verification, record a failed check. Do not assume the position is closed or filled. Keep conflicting employer references visible in your notes. Keep relative age text in its original format. A zero duplicate count in a small test run does not prove that larger runs contain no duplicates.
Sources & further reading
- LinkedIn Help: Repost a closed or expired job
- Indeed Employer Help: Job posting integrity and duplicates
- Google Search Central: Job Posting Structured Data Identifier Guidelines
- Apify Documentation: Dataset Storage Guide
- Apify Actor: LinkedIn Jobs Scraper
- Apify Actor: Indeed Jobs Scraper
- Apify Task Example: Export LinkedIn Jobs to CSV or Excel
- Apify Task Example: Indeed Reposted Job Evidence Dataset
- Reddit csMajors Discussion: LinkedIn Reposted Jobs
- Reddit Recruiting Hell Discussion: Tracking Job Postings
By Chronometrica · Updated
Back to top ↑