Chronometrica publishes the owned Actor compared in this article. An Actor is a hosted program that collects data. A Task is a saved input preset for an Actor.
The reader’s task is to pull public Instagram profile data into n8n. That need appears in this public n8n discussion. The discussion supplies a reader question. It is not a vendor endorsement or a performance test.
Both Actors support bulk public profiles and can be called through n8n. There is no exclusive integration advantage here. This comparison uses public product documentation checked on October 20, 2026. No new collection run or matched performance test was made for it. Chronometrica documentation, Apify documentation.
Choose the output contract before the Actor
An output contract describes the fields in a result row and how to read them. Choose this contract before you build the n8n mapping. The mapping connects returned fields to columns in your destination table.
Start with the next task that needs the data. A report might require a profile ID and follower count. A review table might accept an identity record with missing counts. These tasks need different acceptance rules, even if they use the same source profiles.
Use six decision points to compare the fit:
| Decision point | Chronometrica | Apify Instagram Profile Scraper |
|---|---|---|
| Required input | `startUrls`: 1–1,000 public profile URLs or handles | Bulk public profiles |
| Required output unit | One result row per unique input, with a result state | Broader profile data; check the required row rules |
| Missing-data rule | Preserve unknown values; route with `status` and `statusReason` | Preserve unknown values; check required fields |
| Needed fields | Input echo, `channelUrl`, `channelId`, `countPrecision`, `observedAt`, and result status | Profile metadata, recent content, related accounts, and a paid About section |
| Main limit | A result state does not guarantee complete profile data | Confirm required fields and add-on scope |
| Condition that changes the choice | Use when the smaller contract covers the table | Use when richer fields are required |
Product scope in this table comes from the checked public contracts. Missing-data handling is a workflow rule that you must apply. An undocumented feature is not proof of an absent feature. Chronometrica contract, Apify contract.
A required field is one whose absence prevents the next task from working. Keep that definition clear. Optional fields can add context, but they should not replace the requirements that drive this choice.
What Chronometrica’s checked row provides
Chronometrica documents input echo, `channelUrl`, `channelId`, `countPrecision`, `observedAt`, `status`, and `statusReason`. Its schema accepts up to 1,000 supplied public profile inputs. Duplicate inputs are checked once. Each unique input creates one result row and adds usage. Public Actor documentation.
These parts have separate uses. Input echo retains the submitted source so you can connect a result to its request. `channelUrl` holds the canonical profile URL, which is the standard URL returned for the profile. `channelId` holds the profile identity used to match records.
`countPrecision` supplies precision information for the count values. `observedAt` records when the observation was made. `status` describes the result state, and `statusReason` gives its reason. These are documented fields, not a promise that every requested profile will return every desired value. Field documentation.
Keep these fields together in your destination. A count needs its precision and observation time. A result state needs enough context for the review step. An identity needs a connection to the source that you submitted.
Do not use the submitted URL and canonical URL as the same field. The first records your request. The second records the profile URL identified by the result. Store them separately, even when their text matches.
That separation also makes later review easier. You can inspect what you asked for without changing the returned identity. You can then apply your identity rules to the returned record.
Write the destination table first
Before you configure either Actor, list the columns that n8n must write. This is the table used by the next step, such as a report or a review queue.
For a small profile dataset, the columns might include the submitted source, profile ID, canonical URL, required counts, count precision, observation time, result state, and result reason. These are proposed table columns. They are not additional Actor field names.
Mark each column as required or optional. Then write one clear acceptance rule. For example, a report may require a usable profile ID and a follower count. A separate identity task may accept a record without that count.
Define what happens when a required value is missing. Send the row to review, hold the next step, or use another stated rule. Do not let the destination choose the rule through an unnoticed default.
A blank cell, a null value, and zero can produce different results in later calculations. A null value represents missing data in many data systems. Zero is a number. Choose a form that keeps an unknown value unknown when n8n writes it to the destination.
Finally, compare each required column with the documented output. If a required field sits outside the smaller contract, reconsider the Actor before you build the rest of the flow. This avoids a mapping that works but cannot supply the next task.
Map identity, counts, and result states separately
Use three checks for the mapping. Each check answers a different question.
- Connect the result to its input. Preserve your submitted source list. Map input echo separately from `channelUrl`, and use `channelId` for identity matching when it meets your table’s rules.
- Keep count context. Store required counts with `countPrecision` and `observedAt`. Keep the returned precision information as supplied.
- Route by result state and required fields. Use documented `status` values and retain `statusReason`. Accept a row only when it also meets your table’s requirements.
Do not join results to inputs by row position alone. Chronometrica checks duplicate inputs once per unique input. A repeated input therefore does not require a separate returned row for each repeated entry. Keep the original list so you can connect its entries to the unique results. Input rules.
Do not label a count exact unless its documented precision supports that meaning. Keep the observation time with it so later readers know when the value was observed. Output fields.
A branch sends rows down different workflow paths under a stated rule. One branch can accept rows that meet the table’s needs. Another can send unresolved rows to review. Use the actual documented status values when you set these rules. Do not invent status names.
Check field completeness as well as status. A result row can explain what happened without containing every value your report needs. A missing follower count must remain missing. Zero cannot stand in for an unavailable value or a failed lookup.
A fictional n8n decision
This example is fictional. It is not a test, a buyer quote, a live dataset, or a measured cost result.
Suppose a team needs a public creator table in n8n. Every accepted record needs a profile ID, canonical URL, follower count, observation time, and result state. The team also stores the submitted source and count precision.
Its next step does not require extra account context. It needs a small profile snapshot that a reviewer can inspect. Chronometrica’s documented contract is a suitable choice for that stated need. Actor contract.
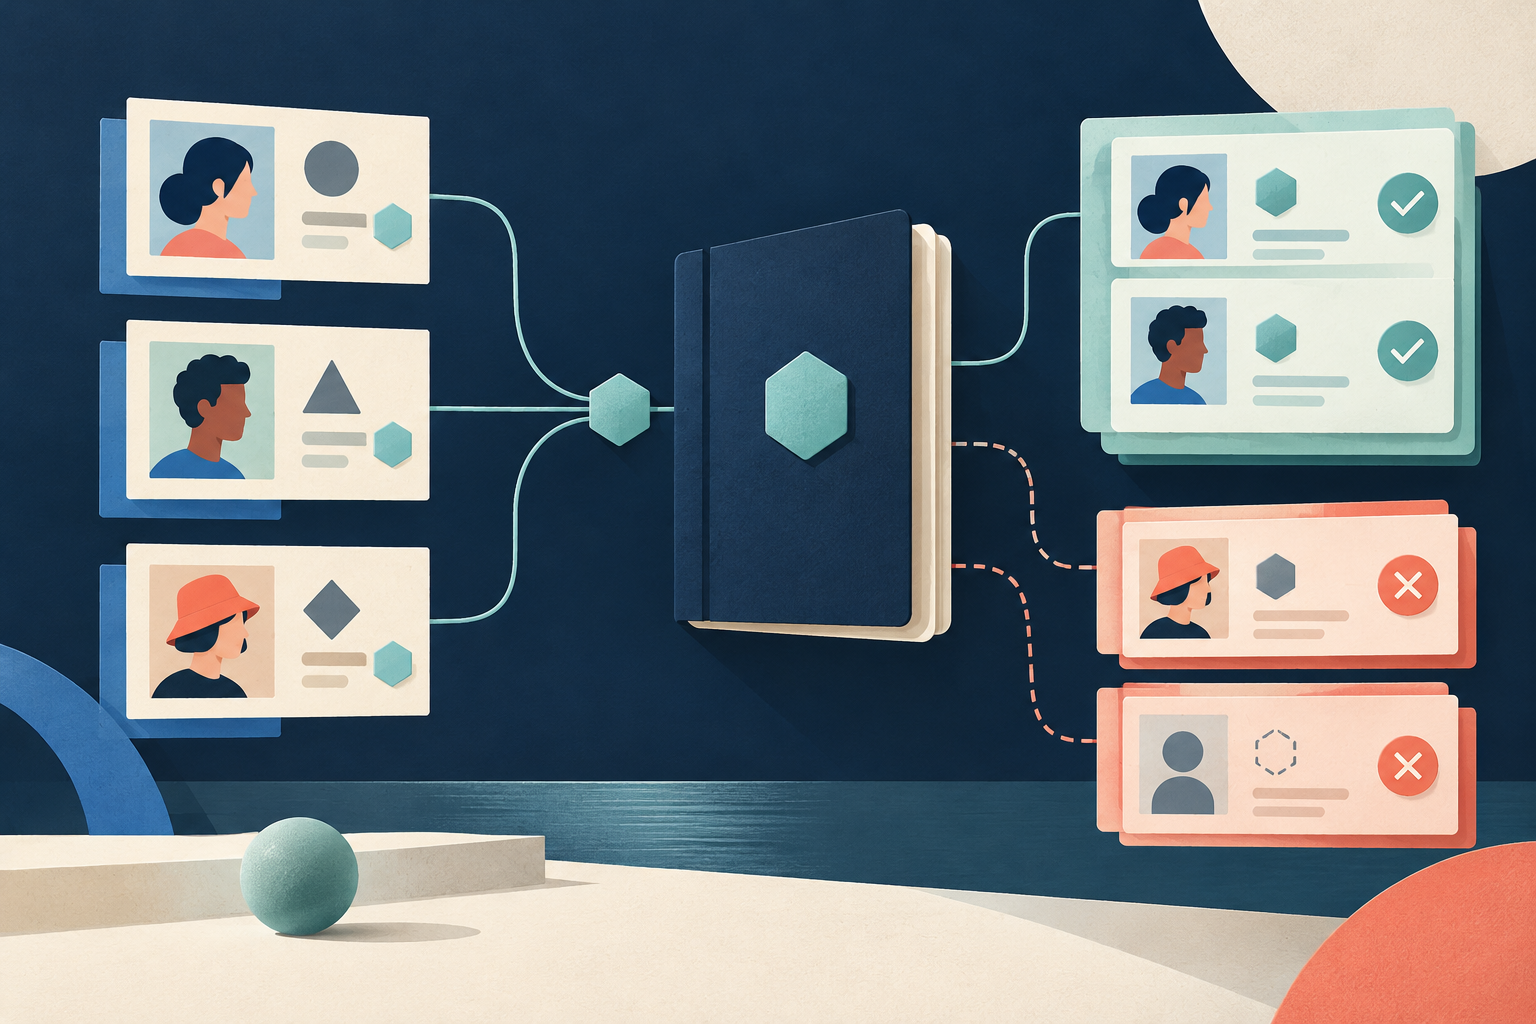
The fictional flow submits three intended public profiles. For each returned row, it checks identity, the required count, and the result state. A row that meets all requirements enters the creator table. A row with a missing required count goes to review. The count remains unknown. An unresolved identity also goes to review.
The team checks the output unit: one unique input creates a checked result state. That state does not guarantee complete profile data. Receiving a row starts the acceptance check; it does not finish it.
Now suppose the next task requires the alternative’s About section or related-profile data. The team considers that richer contract before extending its mapping. The required field changes the choice. Apify profile scope.
This example shows how to choose by fields and handle incomplete rows. It establishes no result about speed, uptime, accuracy, or savings.
Prepare the input and check one intended profile
The published Instagram profile n8n automation Task is a starting preset. Its page check returned HTTP 200 and confirmed the intended Task title. That check does not establish the current saved input. Apply the current-schema input before a run.
This minimal input passed static checks against the checked public schema. Static checks examine input shape without running collection. The checks covered field names, required fields, allowed choices, supplied list sizes, string patterns, and numeric bounds. They did not confirm that the example source is available now. Actor input schema.
{
  "startUrls": [
    "https://www.instagram.com/mrbeast/"
  ]
}Replace the example with one intended public profile. The checked schema accepts a `startUrls` array with 1 to 1,000 strings. Public profile URLs or handles are supported inputs. Input requirements.
Then use this small acceptance check:
- Choose one intended source. Use a public profile that belongs in your workflow. A default example cannot establish whether your intended source works.
- Apply the current schema. Start with one input so you can inspect its result closely.
- Inspect the returned fields. Find input echo, `channelId`, `channelUrl`, required counts, `countPrecision`, `observedAt`, `status`, and `statusReason`. Compare them with your table requirements.
- Inspect both routing rules. Confirm that acceptance requires every mandatory field. Confirm that review preserves unknown values and the result reason. One returned row may not exercise both paths.
- Write one mapped record. Inspect the stored record. Check that identity, missing values, precision, and observation time keep their meaning.
- Decide whether to expand. Continue when the fields fit and the mapping works. Change the Actor choice if a mandatory field falls outside its scope.
This check can reveal a wrong mapping or a destination that replaces missing values with zero. It cannot establish long-term uptime or comparative performance from one profile.
Keep the question narrow: can this returned record support the next task? For the full identity analysis method, use How to Remove Duplicate Instagram Profiles From a Creator List. That guide handles repeated identities. This comparison chooses the collection contract before those records enter that process.
Keep the limits in the decision
The evidence supports a choice by documented scope. It does not prove better uptime, scaling, speed, accuracy, reliability, or coverage. No new price calculation supports a lower-total-cost claim.
An owned audit on October 19, 2026 classed Chronometrica’s Actor as healthy. Those small controls do not prove comparative performance. The public field contract remains the basis for the recommendation. Chronometrica Actor.
This profile workflow does not provide recovered history, follower lists, direct messages, or automatic outreach. Contact facts are available only when publicly exposed. For that separate task, see the public bio contact guide.
The main switch condition is a required field outside the smaller snapshot. Keep that condition in your workflow requirements. When the next task changes, check the field list again before you expand the flow.
Sources & further reading
- Chronometrica Instagram Channel Scraper — public documentation and input schema checked October 20, 2026; supports the stated fields, 1–1,000 supplied inputs, duplicate-input rule, and usage unit; minimal input passed static checks only; no new collection run or matched performance test; the October 19 owned audit classed the Actor as healthy, but small controls do not prove comparative performance
- Apify Instagram Profile Scraper — public documentation checked October 20, 2026; supports the stated broader profile scope and paid About add-on; no matched run, price comparison, or inference that undocumented features are absent
- Public reader question about Instagram profile data in n8n — demand evidence supplied for the October 20, 2026 brief; separate page-check date not supplied; establishes the workflow question, not a vendor endorsement or verified benchmark
- Instagram profile n8n automation Task — supplied page receipt records HTTP 200 and the intended Task title; separate receipt check date not supplied in the October 20, 2026 brief; starting preset only; current saved input is not proved, and no run was made for this comparison
- How to Remove Duplicate Instagram Profiles From a Creator List — existing guide supplied with the October 20, 2026 brief; separate check date not supplied; covers identity matching rather than this named Actor choice
By Chronometrica · Updated
Back to top ↑