Set up your collection plan
The saved public Task input uses three sample queries, `expandQueries` set to false, a shared `maxResults` cap of 150 unique videos, `resultsPerQuery` set to 50, `maxPagesPerQuery` set to 1, and `searchDistribution` set to "balanced". Replace those sample queries with your target terms before running a full panel.
To verify your setup under public Search build 1.1.5, start with a bounded pilot run. Replace the sample query list with one intended term. Set `expandQueries` to false, `maxExpandedQueries` to 0, `maxResults` to 2, `resultsPerQuery` to 2, `maxPagesPerQuery` to 1, and `searchDistribution` to "balanced".
A baseline check using "python tutorial" returned two metadata rows with post IDs, post URLs, author IDs, handles, publication dates from May and August, and an OUTPUT stop reason of `max_results_reached`. This pilot confirms basic search fields and provenance, but it is not a multi-query trend benchmark or ad campaign test.
Native dataset fields and run evidence
Native dataset records include `postId`, `postUrl`, `authorId`, `profileHandle`, `publishedAt`, and `observedAt`. Search provenance fields track query context: `rootQuery` is the original family, `query` is the executed search term, and `querySource` identifies the origin of that term. The `pageIndex` and `pageRank` fields record position on the collected source page. The `status` and `statusReason` fields report item-level outcome states. Optional fields remain null if missing in the source.
The `OUTPUT` object provides run evidence rather than an automated query mapping. Key fields include:
- `queriesSearched`: Array of terms actually executed.
- `queryPlans`: Planned list of query, root, and source definitions.
- `effectiveResultsPerQuery`: Lowered per-term saved video limit calculated during balanced distribution.
- `rowsSaved`: Total unique videos written to the dataset.
- `duplicatesSkipped`: Candidate videos omitted by global deduplication.
- `stopReason`: Overall run stop state, such as `max_results_reached`.
- `sourceStatusCounts`: Aggregated source states, such as `{ok: 1}`.
- `status` and `statusReason`: Top-level execution result, such as `status: "ok"` and `statusReason: null`.
In the single-query control run, `OUTPUT` reported `stopReason: "max_results_reached"`, `rowsSaved: 2`, `sourceStatusCounts: {ok: 1}`, `status: "ok"`, and `statusReason: null`.
A useful fraction is defined as relevant reviewed known-ID videos divided by the comparable reviewable candidate sample for that attempted term; failed or unattempted terms have no valid fraction.
Set up your collection plan
- Define your research question and query families before searching. Group terms only when they represent the same concept and keep an explicit query list.
- Set your shared `maxResults`, `resultsPerQuery`, `maxPagesPerQuery`, expansion choice, and `searchDistribution`. Turn expansion off when comparing an exact fixed list. A shared `maxResults` acts as a total saved-video cap across all queries, while `resultsPerQuery` caps individual terms.
- Choose balanced distribution when you need a planned share across terms. Choose sequential distribution only when filling earlier terms first is your goal. Balanced distribution may lower the `effectiveResultsPerQuery` to share the total limit, but it offers no guarantee that quotas will be filled or that unused allocation will reallocate.
- Separate your planned budget from your actual useful data. Record attempted status, saved rows, known video IDs, duplicates, missing identity, and source failure states. Zero useful rows after a source failure indicates unknown availability, not zero topic interest.
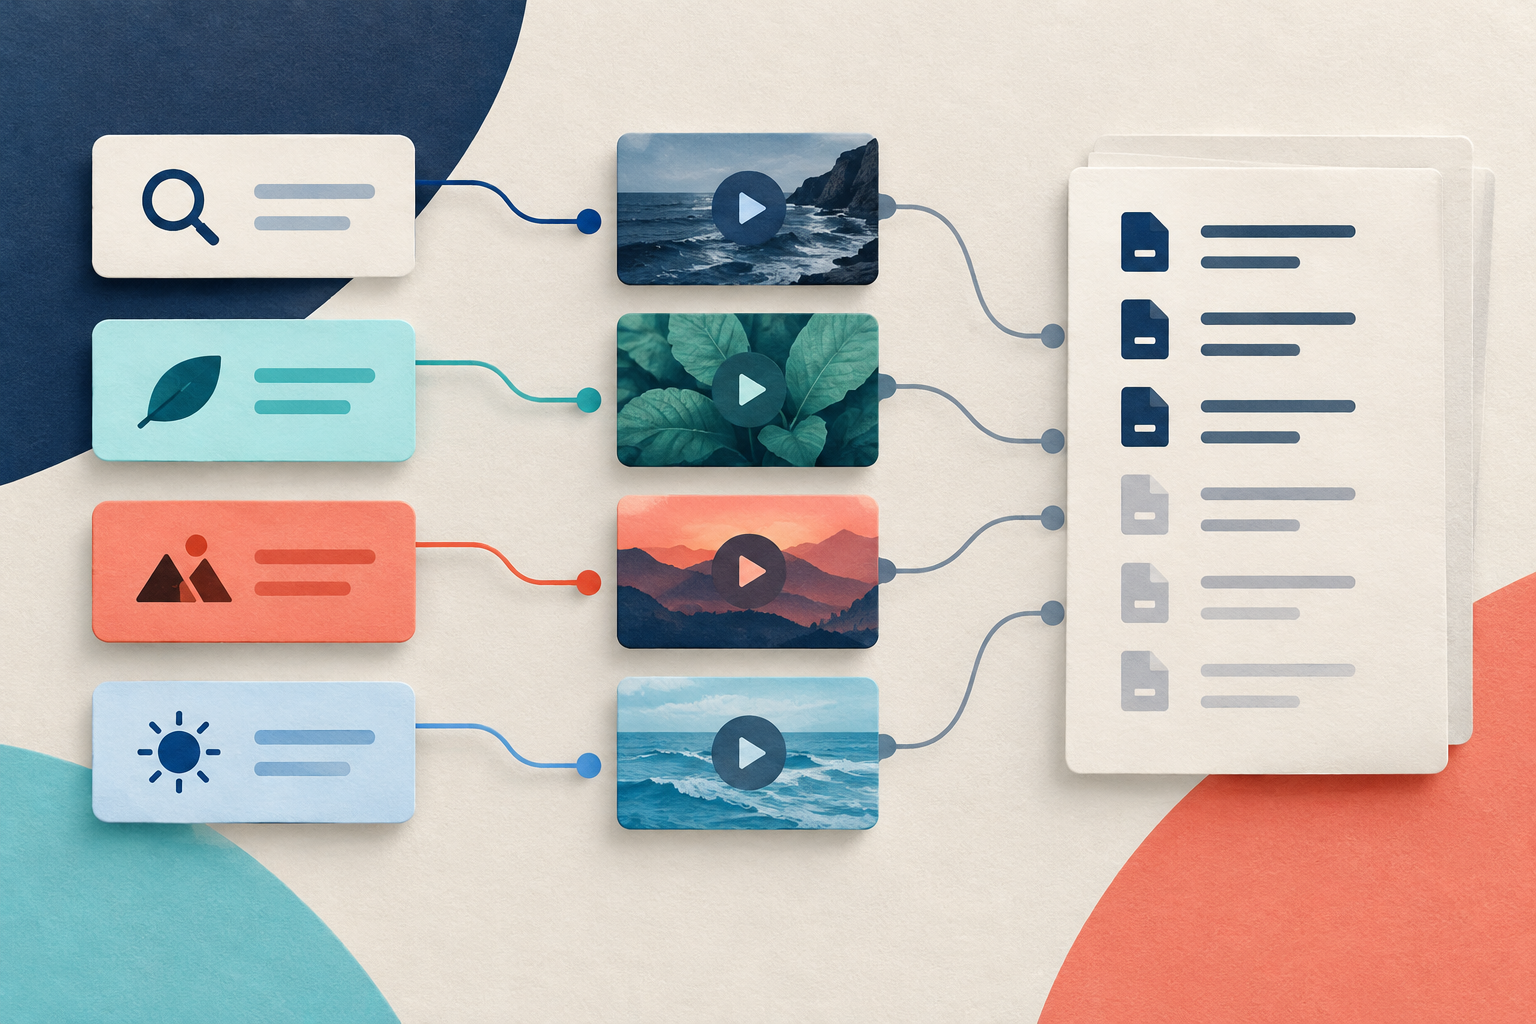
- Preserve provenance and handle global deduplication carefully. Provenance means keeping the exact saved source and collection time recorded in `observedAt`. Native global deduplication saves a video only once under its first observed query. To capture every query appearance, keep separate per-query run ledgers.
- Apply the same manual relevance rule to all groups. Distinguish candidate videos from useful items by checking exact `postId` and `postUrl` values. Calculate useful fractions using only attempted, usable data, while treating failed or unattempted terms as unknown.
- Report gaps before comparing groups. Mark unattempted terms as `not_attempted` rather than zero, and keep source cap limits visible. Never rank query groups by raw total counts alone when collection limits or failures differ.
- Save your query plan and actual sample ledger. Review `OUTPUT` fields like `queriesSearched`, `queryPlans`, `rowsSaved`, `duplicatesSkipped`, and `stopReason` to record exact stop evidence before performing trend or creative analysis.
Original fictional collection ledgers
All values below are original fiction created to illustrate collection budgets, stop states, and global deduplication limits. They do not represent live product benchmarks or pilot results.
Consider three terms A, B, and C with `maxPagesPerQuery` set to 1, expansion off, `maxResults` set to 6, and requested `resultsPerQuery` set to 6.
- Balanced run: The reported `effectiveResultsPerQuery` is 2, creating a planned limit of 2 saved videos per term. If every term returns 2 distinct relevant videos, the ledger shows A=2, B=2, C=2, saving 6 total videos. The useful fraction is 2/2 for each term.
- Sequential run: The configured per-term limit is 6 for terms A, B, and C. Term A returns 6 saved videos and fills the shared `maxResults` cap of 6. Terms B and C are never attempted. The ledger records Planned Max 6 for each term, with A=6 saved, B=0 saved (`not_attempted`), and C=0 saved (`not_attempted`). Logging 0 saved rows for B and C is bookkeeping; their sample availability remains unknown.
- Source failure in balanced run: Term A saves 2 useful videos (2/2 fraction), term C saves 2 useful videos (2/2 fraction), and term B encounters a source error. Term B records 0 saved rows, 0 useful rows, and an unknown relevance fraction. The label `source_failed` is a reader ledger notation, not a native dataset enum.
| Query Term | Mode | Planned Max | Attempted | Saved Rows | Useful Rows | Stop Reason / State |
|---|---|---|---|---|---|---|
| Term A | Balanced | 2 | Yes | 2 | 2 | Per-query limit reached |
| Term B | Balanced | 2 | Yes | 2 | 2 | Per-query limit reached |
| Term C | Balanced | 2 | Yes | 2 | 2 | Per-query limit reached |
| Term A | Sequential | 6 | Yes | 6 | 6 | Shared `maxResults` reached |
| Term B | Sequential | 6 | No | 0 | Unknown | `not_attempted` |
| Term C | Sequential | 6 | No | 0 | Unknown | `not_attempted` |
| Term A | Balanced (Fail B) | 2 | Yes | 2 | 2 | Per-query limit reached |
| Term B | Balanced (Fail B) | 2 | Yes | 0 | Unknown | `source_failed` |
| Term C | Balanced (Fail B) | 2 | Yes | 2 | 2 | Per-query limit reached |
Fictional query membership ledger
A separate fictional query run evaluates video appearances across terms without global deduplication filtering out overlaps.
| Video ID | Term A Membership | Term B Membership | Term C Membership | Retained First Query |
|---|---|---|---|---|
| V1 | Present | Absent | Absent | Term A |
| V2 | Present | Present | Absent | Term A |
| V3 | Absent | Present | Absent | Term B |
| V4 | Absent | Absent | Present | Term C |
| V5 | Absent | Absent | Present | Term C |
This membership table contains 6 total memberships across 5 distinct video IDs. A single globally deduplicated export retains V2 only under Term A. Retaining Term A provenance for V2 does not prove V2 was absent from Term B. Full query membership can only be tracked by saving separate bounded run ledgers for each query.
Sources & further reading
By Chronometrica · Updated
Back to top ↑