Collection setup
The Reddit Comments Scraper returns comment rows from known public threads rather than separate post rows. The input requires `postUrls` (1 to 50 public thread URLs) and `maxCommentsPerPost` (1 to 500 per post, default 100, preset 250, pilot one known thread cap 3).
Each row export includes exact fields: `postId`, `commentId`, `parentId`, `depth`, `body`, `status`, `unavailableFields`, and `observedAt`. Dataset row status values are strictly `ok`, `deleted`, and `removed`. Partial and failed run or input states remain separate from row status values.
The OUTPUT `isComplete=true` flag indicates finished processing in this control, while overall input results remain partial. `inputResults` has `status`, `reason`, `commentsFound`, and `commentsSaved`, and `hiddenBranchesRemaining` can be null. A current pilot returning three body-present IDs with `parentId`, `depth`, and branches unavailable—and no removed/deleted rows—proves bounded collection rather than a live moderation panel or complete history. A missing author differs from a missing body; never infer cause or recover missing words.
Open the Reddit Moderation Research Dataset Task to inspect the public run preset.
Eight steps to record missing text
- Define the research unit and snapshot scope before counting. Look at observed comment identities in specified threads at one collection time. Keep unresolved IDs separate. Do not mix source displayed counts or unknown branches into an observed-row denominator.
- Keep the untouched source export and output file. For each known identity, retain its status, body availability, unavailable fields, and observation time. Do not delete a removed or deleted position simply to make a clean text table.
- Create a text-analysis working subset containing genuinely available bodies. Keep placeholder text out. Preserve a missing author as a separate fact. An anonymous visible body can still be available text under your study rule.
- Report observed known positions, available text positions, removed markers, deleted markers, and other unavailable or uncertain positions. Use disjoint categories for a simple count, and state your assignment rule. If states overlap or identities conflict, review them instead of forcing the sum.
- Keep the analysis denominator beside every percentage. A share among text-available rows answers a different question from a share among all observed positions. Neither estimates the unobserved full discussion.
- For repeated checks, join only known source comment identities and compare their observed states. Keep newly observed and no-longer-observed keys separate from a confirmed same-key state transition. Absence in a later capped snapshot does not prove deletion.
- Do not attribute a state change to moderators, authors, policy, censorship, or a sentiment class without independent source evidence. An unavailable body cannot be classified by its neighboring replies alone.
- Deliver a snapshot availability table and, where supported, a matched-key transition table. Keep collection limits and unknowns visible so another researcher can understand which text entered the analysis.
All identities, states, and metrics in these tables are fictional authored artifacts and do not represent measured real-world moderation outcomes.
Snapshot A: Ten-Key Observed State Table (Fiction)
| Key ID | Source Status | Body Availability | Count / Share |
|---|---|---|---|
| C1–C7 | ok | Available | 7 rows (70%) |
| C8–C9 | removed | Unavailable | 2 removed markers (20%) |
| C10 | deleted | Unavailable | 1 deleted marker (10%) |
- Denominator details: Available text share is 7/10 = 70%; unavailable text is 3/10 = 30%. An invented sentiment classifier labels 4 of 7 available bodies positive; 4/7 roughly equals 57.1% as a share of analyzable text only. Do not write 40% of all comments positive, and do not assign labels to unknown bodies.
Snapshot B: Matched Ten-Key State Table and Transition Ledger (Fiction)
Snapshot B: Grouped Matched-Key Table (Fiction)
| Key ID | SnapshotAstatus | SnapshotBstatus | Transition |
|---|---|---|---|
| C1–C6 | ok | ok | unchanged |
| C7 | ok | removed | changed |
| C8–C9 | removed | removed | unchanged |
| C10 | deleted | deleted | unchanged |
- Snapshot B metrics: 6 available, 3 removed, 1 deleted (9 unchanged keys plus 1 changed key). This fictional table illustrates denominator arithmetic and does not represent real-world moderation outcomes.
- Snapshot B metrics: 6 available, 3 removed, 1 deleted. Text availability is 6/10 = 60%, down 10 percentage points from Snapshot A. This is not a measured moderation effect, removal cause, or community trend.
Snapshot C: Scope Comparison Note (Fiction)
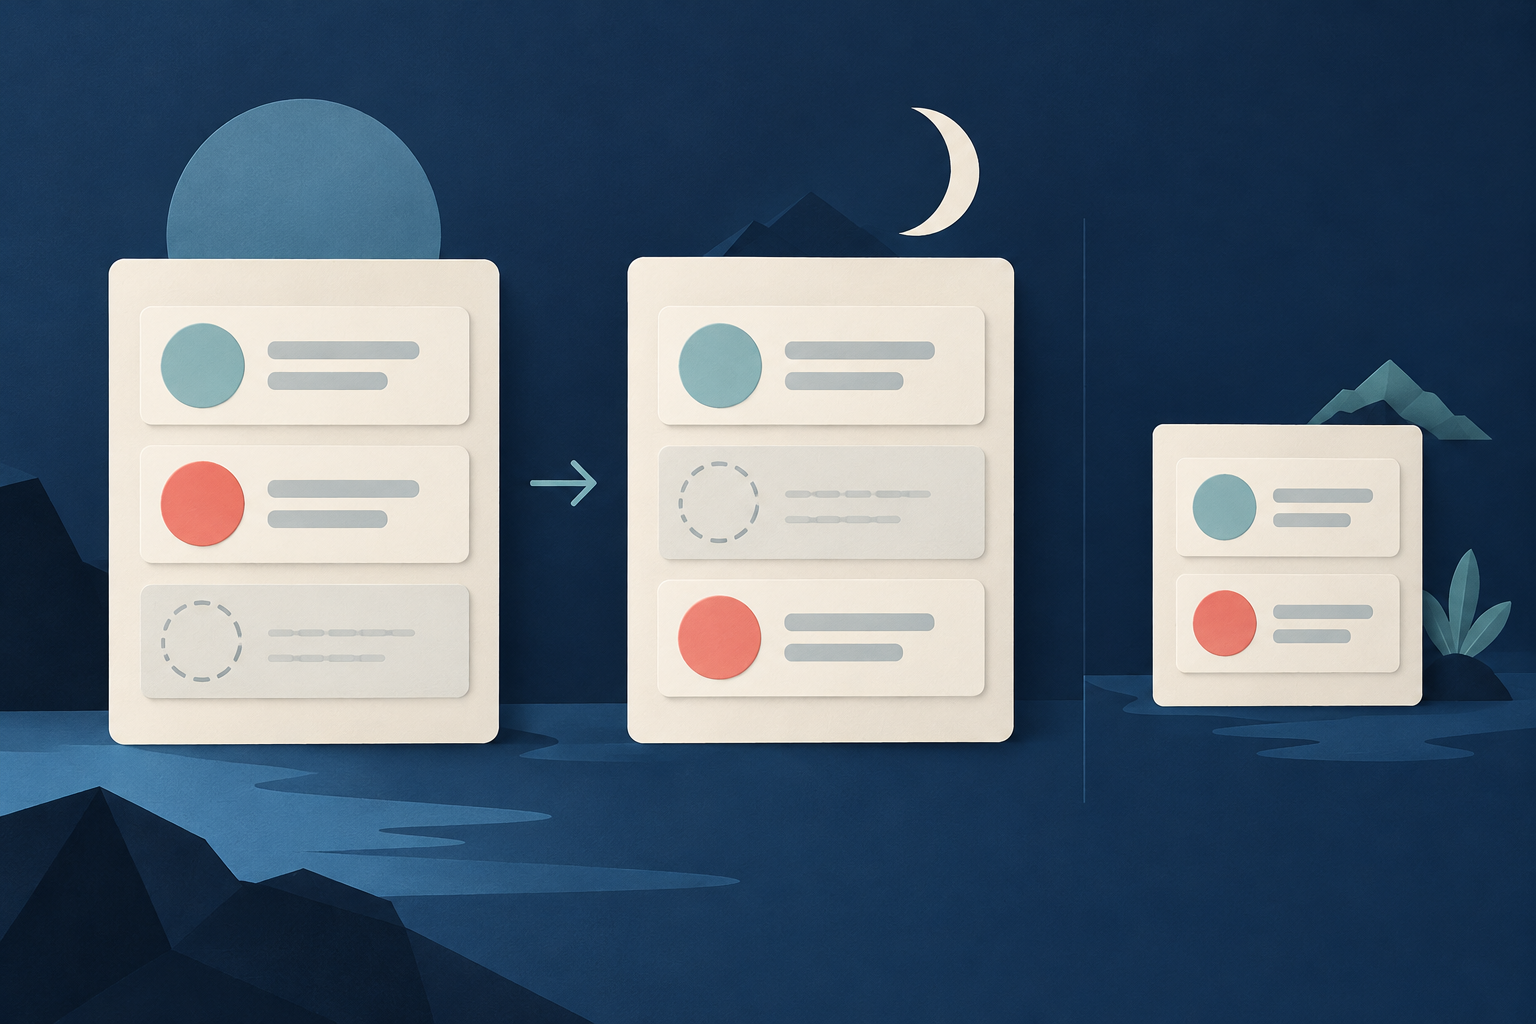
- Snapshot C returns 8 keys total (7 old keys retained plus new key C11; C1, C2, and C3 are omitted).
- C1, C2, and C3 absence in this limited snapshot is not proof of deletion.
- Body categories are unsupplied for C, so compute no availability rate.
Sources & further reading
By Chronometrica · Updated
Back to top ↑