Collection setup
Open the YouTube Search Scraper or the YouTube Content Idea Research Task. The current preset inputs include queries (plural), maxResults 150, resultsPerQuery 40, maxPagesPerQuery 2, enableQueryExpansion set to true, and enrichWithVideoMetrics set to true.
For the pilot, replace queries with one viewer question, set maxResults to 2, resultsPerQuery to 2, maxPagesPerQuery to 1, and disable query expansion and metric enrichment with enableQueryExpansion equal to false, enrichWithVideoMetrics equal to false, and optional enrichMissingChannelFields equal to false. maxResults is shared within one run across its queries, while resultsPerQuery caps each search, and separate runs have separate maxResults caps.
Retain the exact output fields: rootQuery, query, querySource, pageIndex, pageRank, postId, postUrl, postType, isShort, title, description, publishedAt, channelId, status, statusReason, and observedAt. Source rank indicates position, not demand or content quality. The current two-candidate control used no expansion or enrichment, and publication dates were null. It verifies bounded source shape, not idea quality or actual reviewed video content. Missing dates remain unknown and cannot be inferred as zero. Actual answer review is manual.
Collect and map viewer questions
- Choose one viewer and a real question you can answer. Write the action, starting knowledge, and boundary that matter. Convert that question into two or three plain search phrases. These are proposed terms, not validated search volume.
- Collect a small sample per phrase with an explicit query, cap, and time. Preserve source video identities and duplicate query context. Avoid comparing Shorts and long tutorials as if their depth were equal without noting format.
- Review each video's actual answer where available. A title can promise one answer while the body misses the key condition. If you cannot inspect the video, keep coverage unreviewed rather than infer it from title or description.
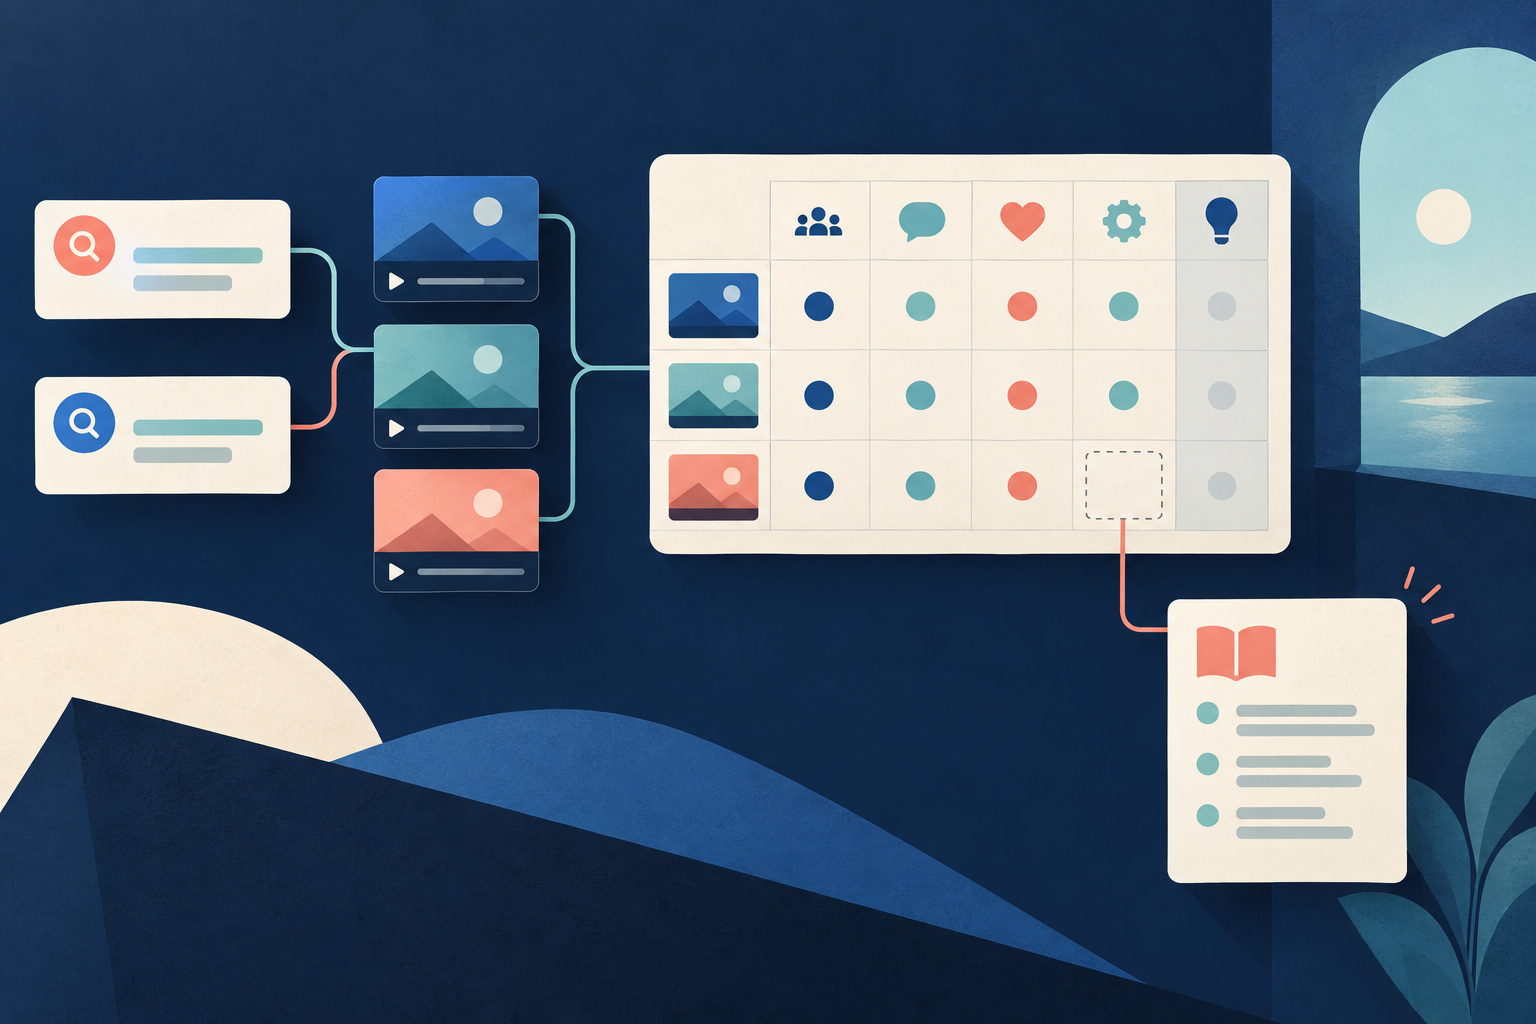
- Make a question-part matrix. Rows are viewer requirements; columns are reviewed source videos; cells are answered, partial, missing, or unreviewed, with source passage or scene note. The labels are reader-created, not Actor output.
- Look for a specific condition or step the observed examples do not explain. Distinguish a gap in your sample from absence across YouTube. An uncommon question may have one excellent answer outside your sample; it does not prove under-served demand.
- Verify your proposed answer with your own checked method, example, or primary source. Do not publish a contrarian claim only because it differs from the collected videos. The aim is clearer useful teaching, not copied structure or unsupported novelty.
- Write an original teaching outline: direct answer, required condition, worked example, check or failure case, and final action. Use the keyword naturally because it names the question; do not stuff terms or promise traffic.
- Save the coverage matrix and source limits with the idea. You may need your own audience feedback or search demand data to prioritize it commercially; this dataset alone does not do that. The final result is a justified question-specific outline, not a winning keyword.
Question-part matrix example
To see how this works, look at a fictional test. The viewer is a new spreadsheet user. The question is how to compare two exports without missing changed rows. Query family A uses compare CSV files. Query family B uses find changed spreadsheet rows. Candidate appearances show five total spots across four unique videos. Human review covers video one, video two, and video four. Video three remains unreviewed. Actual viewing is manual. Null dates or metrics remain unknown, not zero.
The requirements are matching stable keys, comparing values, handling missing keys, and checking duplicates.
| Requirements | Video One | Video Two | Video Four | Video Three |
|---|---|---|---|---|
| Match stable keys | Answered | Partial | Answered | Unreviewed |
| Compare values | Answered | Partial | Answered | Unreviewed |
| Handle missing keys | Missing | Missing | Missing | Unreviewed |
| Check duplicates | Missing | Missing | Answered | Unreviewed |
Video one answers the first two rules but misses the last two. Video two shows line-by-line comparison only, making all four requirements at best partial or missing because row order can change. Video four answers stable keys and duplicates but omits the missing-key decision. Video three cells are unreviewed, not missing.
The observed sample gap is that none of the three reviewed videos demonstrates the missing-key review ledger. This is not a claim that YouTube has no such video.
Original teaching outline and toy example
The original outline has five parts. The direct answer is to match known row keys and hold missing keys for review. The required condition is that keys must identify the record. The worked example uses two invented exports with a changed order. The check is that a missing key must not be assigned by position. The final action is to create changed and unresolved tables.
Consider old rows where key one has value ten and key two has value twenty. Consider new rows where key two has value twenty-one, key one has value ten, and an unknown key has value twenty.
Old: K1=10, K2=20
New: K2=21, K1=10, Unknown=20Confirm key one is unchanged. Confirm key two changed from twenty to twenty-one. Leave the new unknown row unresolved. Do not match the unknown row to key two just because twenty looks like the old value. The final artifact contains four video coverage columns, three reviewed source counts, one unreviewed column, and the five-part original outline. No real content performance, search volume, or estimated view count follows.
Sources & further reading
By Chronometrica · Updated
Back to top ↑