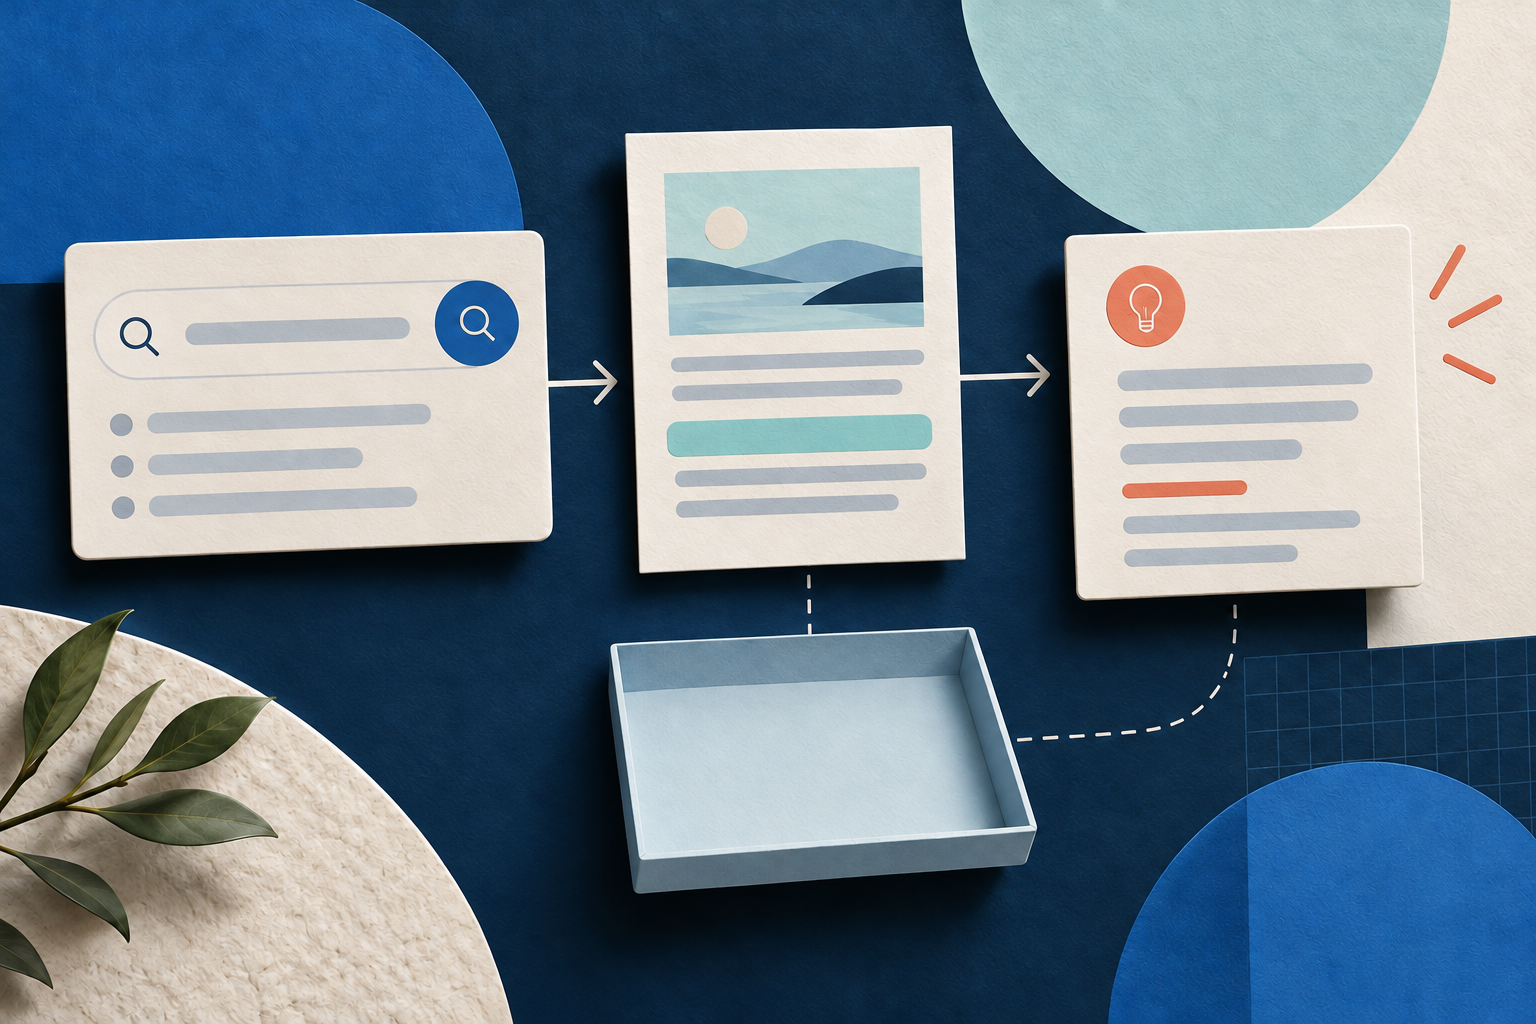
An HTML is the saved page markup. A library is separately installed code used by the reader. A hash is a file fingerprint used to identify the exact saved copy. A None or empty output represents unavailable extraction. Keep fetched input, body, and extraction states separate; a login, challenge, or HTML shell is not an obtained body, and no rendering or hidden access was tested.
Check Main Text Extracted From a Web Page
- Define what the agent needs from the page and which page areas are outside that need. This method addresses extraction quality.
- Use the public Google Search Scraper build 1.0.15 Actor with a Task to discover candidate URLs if discovery is needed. Replace the whole saved three-query sample with one intended search phrase using `queries` ["one intended phrase"], `engines` ["bing"], `maxResultsPerExecutedQuery` 2, `country` "US", `language` "en", `safeSearch` true, and `includeSponsoredResults` false. Native search candidate fields include `engine`, `executedQuery`, `canonicalUrl`, `resultDomain`, `snippet`, `rank`, `page`, and `observedAt`. Output aggregate records include `queriesRequested`, `searchesCompiled`, `executionsPlanned`, `enginesRequested`, `enginesSuccessful`, `enginesFailed`, `pagesAttempted`, `pagesParsed`, `candidatesSeen`, `resultsSaved`, `engineStatusCounts`, `queryResultCounts`, and `stopReason`. The current two-row Bing control returned direct docs.python.org candidate URLs with query, rank 1 and 2, page 1, and observation time, plus one parsed page and stopReason `result_caps_reached`. It verifies bounded candidates only, not destination retrieval, text extraction, or other engines or markets. Only Bing has accepted engine evidence here.
- Fetch a permitted destination page separately and preserve its final URL, retrieval time, content type, and source HTML. The search actor does not do that fetch. Verify that the saved input actually contains the intended article text. Keep `fetch_failure`, `body_not_in_saved_html`, and `extraction_unavailable` separate.
- Run a separate text-extraction library on that saved HTML under a recorded version and options. The original local HTML fixture was tested with installed version 2.0.0 using `trafilatura.extract(html, include_comments=False)`. Note that current documentation describes version 2.3.1, so these version facts must stay separate.
- Define several source checks before accepting the output: required heading or passage, negation or condition, number with its unit, and excluded navigation, footer, or comments. Compare the saved HTML and the returned text. A dropped unit or a missing negation can reverse the meaning.
- Record each check as retained, changed, missing, unwanted_noise_present, or cannot_resolve, with the exact source locator and extracted passage. Count the checked facts only if useful.
- If a critical check fails, review the saved HTML and extraction settings rather than pass corrupted text to the agent.
- Save a compact extraction record: source URL and retrieval context, HTML reference or hash, extractor version and options, output reference, check table, and decision.
Original fictional complete saved-HTML fixture: The saved HTML for "Fictional tray guide" has navigation, sign-in, and footer blocks, an article, and a comment section. The article says "Do not add water until the tray is level" and "Use 12 milliliters of water for this fictional demonstration." The comment and menu contain unrelated words. No destination was fetched live for this fixture.
| Check Item | Saved HTML Content | Extracted Text Output | Status |
|---|---|---|---|
| Required Heading | Fictional tray guide | Fictional tray guide | Retained |
| Negation / Condition | Do not add water until the tray is level | Do not add water until the tray is level | Retained |
| Number and Unit | 12 milliliters | 12 milliliters | Retained |
| Navigation Marker | NavigationMarker | Absent | Reader-created check: unwanted noise absent |
| Footer Marker | FooterMarker | Absent | Reader-created check: unwanted noise absent |
| Comments Marker | CommentsMarker | Absent | Reader-created check: unwanted noise absent |
The installed version 2.0.0 extractor call produced nonempty main text. A hypothetical output like "Add water. Use 12" would fail two checks because the required negation and condition changed and the number unit is missing. A hypothetical empty output would be marked as `extraction_unavailable`, not a zero-fact article.
Sources & further reading
By Chronometrica · Updated
Back to top ↑