A public research question asks how to collect TikTok transcripts for a study. It also asks how to check accuracy and how to analyze the text in R. R is a program for tables and counts. The question shows a need. It does not prove that this method is valid. It does not show how many studies need it. See the public question on TikTok transcripts.
You collect rows with an Actor. An Actor is a hosted data collection program. Hosted means it runs as a service, not as a file on your computer. This Actor is the TikTok Transcript Scraper. A Task is a saved input preset. A preset is a stored set of input choices. The current Task is TikTok Transcript Dataset for Content Analysis. The Actor collects source rows. You do the coding and the counts. A public Task is only a starting input. It does not mean the analysis runs by itself.
What the current collector returns
These public facts were checked on 2026-10-13. The current build is 0.1.36. Each run accepts 1 to 100 known public targets in `startUrls`. A target can be a video URL, a short link, or a numeric video ID. The Actor does not search a profile, a keyword, or a sound page. You must already know the videos.
`preferredLanguages` is an ordered list of public caption languages. The Actor picks the first matching public track. An empty list uses the first public track. It does not translate text. It does not create text from sound that has no caption. It does not collect comments. It does not assign content codes.
The saved Task input is:
{"startUrls": ["https://www.tiktok.com/@hankgreen1/video/7047596209028074758"], "preferredLanguages": []}Replace that sample with your own known public videos. For a one-video pilot, put one URL in `startUrls`. If English is your study language, set `preferredLanguages` to `["en"]`. If your study uses another language, write that language rule and use its code. Do not copy `["en"]` into a study of a different language. An empty list can return some other public track.
One dataset row stands for each submitted input. A failed input still gets a row. Keep that row. It is evidence of the attempt. These fields are exact: `inputIndex`, `inputUrl`, `videoId`, `videoUrl`, `authorHandle`, `durationSeconds`, `languageCode`, `text`, `segments`, `status`, `statusReason`, `isBillable`, and `scrapedAt`. Each segment has `startSeconds`, `endSeconds`, and `text`. TikTok times use those two keys. Use `startSeconds` and `endSeconds` as returned. Keep every `videoId` as text, not as a number. A long ID can change if a program stores it as a number.
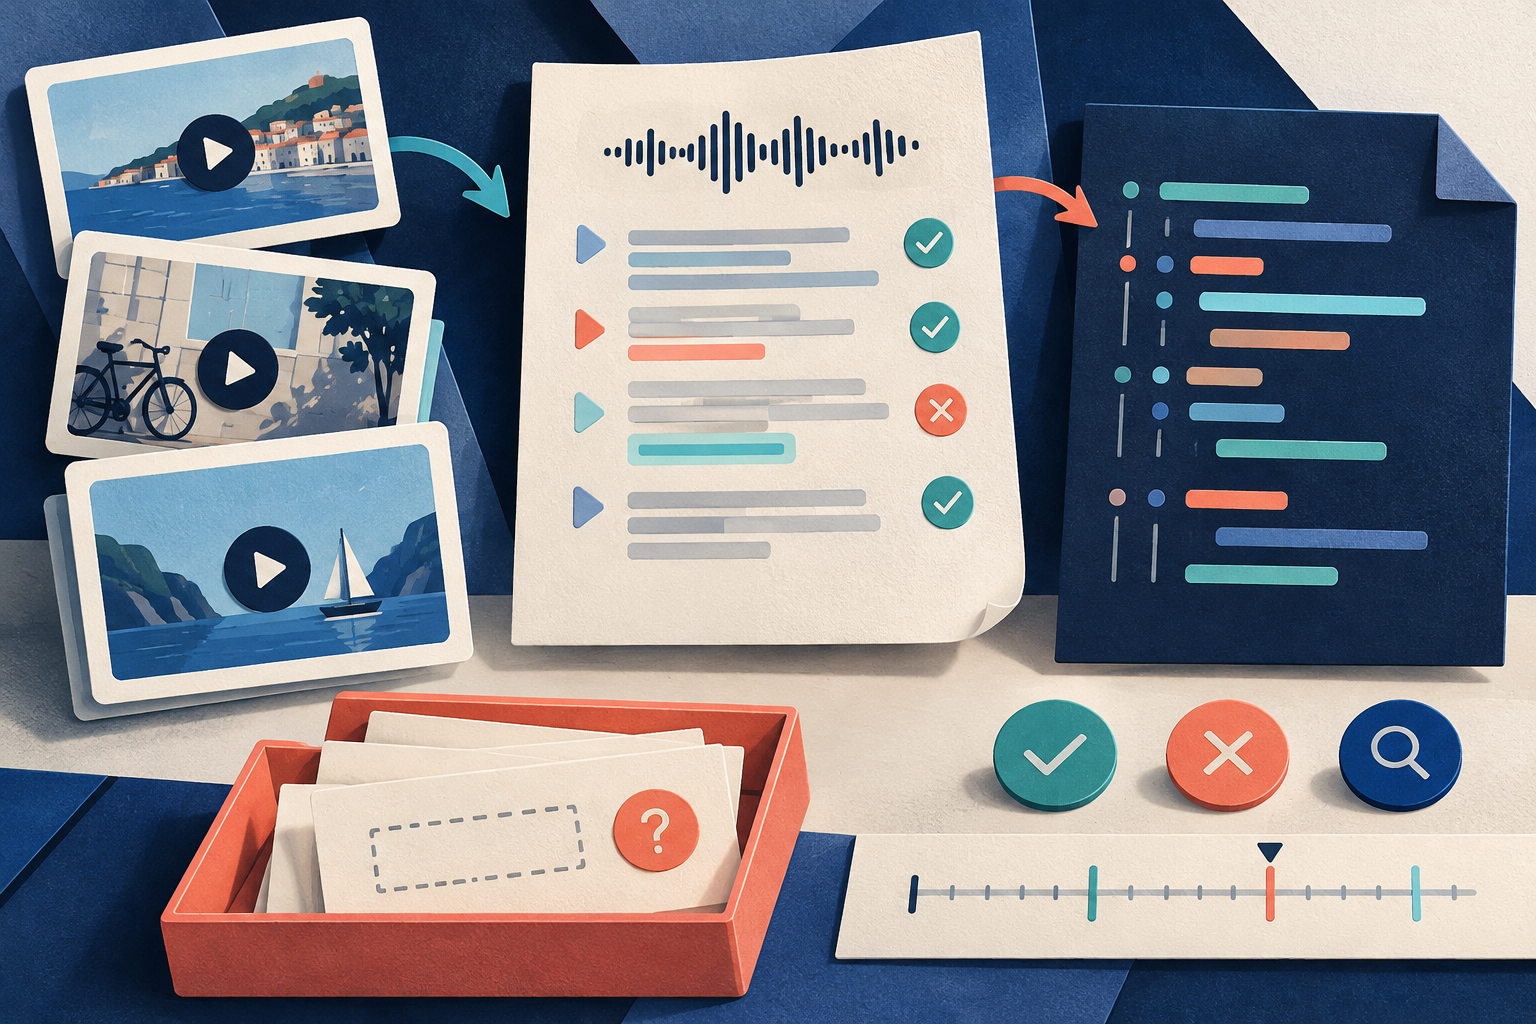
`status` can be `succeeded`, `no_public_captions`, `language_unavailable`, `duplicate_input`, `not_tiktok`, `invalid_input`, `unsupported_url`, `video_unavailable`, `not_public`, or `blocked_or_challenged`. Extraction failures and caption failures can also occur. Success requires text that is not empty. A null or empty transcript with a failure status is not spoken silence. The video may still have speech. You only know that no usable caption came back.
`isBillable` is true only for a successful native transcript result. The field name uses a lowercase b. Other rows stay in the data as evidence. `isBillable` does not describe the whole run. A run can mix true and false rows. Do not call the whole run free.
The run account uses these exact names: `inputsReceived`, `resultRows`, `billableTranscriptRows`, `nonBillableResultRows`, `duplicateVideosSkipped`, and `statusCounts`. This account checks the run. It does not show that your videos represent all creators.
A one-video check on 2026-10-13 used the saved sample. The row succeeded. The video ID was the requested ID, `7047596209028074758`. The language code was `eng-US`. A code such as `eng-US` is a regional caption label. It means English with a United States region tag. It is not a translation. The text was not empty. The row had 12 segments. The segment timing had the `startSeconds` and `endSeconds` shape. No caption words from that video are repeated here. That check proves a public caption path on that one source. It does not prove perfect words. It does not prove that every video succeeds. It does not prove that your content code is valid. Your own pilot is still required.
Eight actions
- Define the question, the code, and the sample
Write one research question. Write one content code you can count. A content code is the feature you mark as present or absent. Choose known video URLs under a rule you can state. State the time period, the language, and the creator scope before you collect.
A sampling ledger is the list of every video you selected. Fill that ledger before you look at captions. Do not select videos only because a caption exists. If you keep only videos with captions, you have changed the sample. Videos with no caption would drop out instead of showing up as missing.
- Declare the counting unit
Choose the unit you will count. The unit can be one video, one caption segment, or a passage you define. In these steps, the counted unit is the video. A segment is a timed piece of caption text. Segments are evidence for the video. They are not extra videos.
Three segments with the same code still count as one video. Write that rule down before the run. Keep the input URL, the returned `videoId`, and your own `selected_video_key`. The study key is yours. It stays the same even if the URL form changes.
- Test one selected video
Run one selected video before any batch. This is a pilot. A pilot is a small test of the whole path. Inspect `status`, `videoId`, `languageCode`, and `text`. The text must be non-empty for a success. If your study language is English, set `preferredLanguages` to `["en"]` on this pilot.
Then compare a short passage with the audio. Also look at the picture on screen. Write down missed words, extra words, and wrong words. A successful row does not prove that the words are accurate. The 12-segment check above only shows that the public path can return a caption. It is not your validation.
- Run the bounded list and reconcile it
Send only your known URLs, up to 100 in one run. A longer selected list needs another run. Match every submitted input to one result row. Use `inputIndex`, `inputUrl`, and `videoId`. Match those rows to the run account.
Check `inputsReceived`, `resultRows`, `billableTranscriptRows`, `nonBillableResultRows`, `duplicateVideosSkipped`, and `statusCounts`. Keep duplicates in the notes, and count that video once. Keep missing captions in the ledger, but outside the success set. Do the same for source-access failures. Those statuses include `video_unavailable`, `not_public`, `blocked_or_challenged`, `unsupported_url`, `not_tiktok`, and `invalid_input`.
Never code empty failed text as "code absent." Empty text means you did not observe the code. It does not mean the code is absent.
- Make a video table and a segment table
Make one row per selected video. Use these columns: `selected_video_key`, `videoId`, `videoUrl`, `languageCode`, `caption_status`, `caption_validated`, `study_eligible`, and `exclusion_reason`. `study_eligible` records whether the video may enter the count. It is not the content code. `caption_validated` records whether you checked the caption against the video.
Use `unknown` when you could not check the caption. Do not write `caption_validated` as no when the true state is unknown. A failed row was not validated. An unfinished review was not validated either.
Keep segments in a second table. Use the video key, `startSeconds`, `endSeconds`, `text`, and a source observation. A segment array inside one spreadsheet cell is a poor export. CSV is a flat text table. A nested list does not fit that flat shape in a safe way. Export JSON first. JSON is a text format that can keep a list inside an item. Then flatten on purpose. Flatten means you make one plain row per segment. Repeat the video key on each segment row. Do not split the text on commas. Sentences contain commas. Leave the raw caption text unchanged. Put every code in new columns.
- Write a small coding rule and try it on fiction
The examples from this step on are fiction. They are not Actor output. Do not paste these IDs into a live input. Their video URLs are unknown.
Write a short rule and give it a version. For a simple exact-word rule, define the word, the letter case, and the word boundary. A word boundary stops a short word from matching inside a longer word. Review ambiguous uses yourself. A keyword rule only finds that pattern. It does not prove what the speaker meant. A point made only by pictures can disagree with the words. Sarcasm can also disagree with the words. Those cases need a person to code them.
The fictional code here is an explicit instruction to measure water. Rule version v1 marks code 1 when validated caption text gives that instruction. The whole word "measure" counts in any letter case. The word "measurement" is a different word. Review it. Do not mark it by the keyword rule alone. Code 0 is allowed only on a validated caption that lacks the instruction. Otherwise the code stays unknown.
- Check a pilot set, then import it in R
Code a small pilot set before a large study. Two people can code it apart from each other. Or you can code it again later and compare. Store `code`, `code_version`, `coder`, `decision_note`, and a timestamp. The timestamp records when the decision was made. Keep raw text in its own column.
R can read a flat CSV. Tell R that ID columns are text. Do not let R guess a numeric ID. The snippet below uses base R only. It uses the fictional rows. It does not add a package. It is not a tested research standard. Here, `denom` is the denominator. The denominator is how many eligible videos you divide by. `NA` means not available. This example uses `NA` for an unknown code.
videos <- data.frame(
  videoId = c("video-v1", "video-v2", "video-v3", "video-v4", "video-v5"),
  study_eligible = c("yes", "yes", "no", "no", "no"),
  code = c(1, 0, NA, NA, NA),
  stringsAsFactors = FALSE
)
stopifnot(is.character(videos[["videoId"]]))
eligible <- videos[["study_eligible"]] == "yes"
stopifnot(!any(is.na(videos[["code"]][eligible])))
code_count <- sum(videos[["code"]][eligible])
denom <- sum(eligible)
share <- code_count / denom`code_count` is 1. `denom` is 2. `share` is 0.5. The `NA` values are unknown codes. They are not zeros. The `stopifnot` line stops the script if an eligible video has an unknown code.
When you export a real CSV, keep the same text check:
videos_from_csv <- read.csv(
  "video_table.csv",
  stringsAsFactors = FALSE,
  colClasses = c(videoId = "character")
)
stopifnot(is.character(videos_from_csv[["videoId"]]))You can test the fictional word rule in base R too:
raw_text <- "I measure the water before I pour it"
hit <- grepl("\\bmeasure\\b", raw_text, ignore.case = TRUE)
ambiguous <- grepl("\\bmeasure\\b", "measurement", ignore.case = TRUE)`hit` is TRUE. `ambiguous` is FALSE. The second result is why a longer word needs a human review rule, not a silent match.
- Report the count with the full outcome ledger
Use only eligible videos as the denominator for the code share. Eligible means `succeeded`, non-empty text, and `caption_validated` yes. Report every selected-video outcome beside that share. Readers must see failures and unfinished rows. Limit the finding to the videos you selected and observed. Do not state it as a result for all creators. Do not state it as a result for all political speech.
Missing captions can change a conclusion. This article stops at the ledger. It does not teach how far those missing rows can move a result.
Fictional five-video count
The same fiction continues here. V1 through V5 are made-up study labels. The `videoId` values are made-up text labels. They are not live TikTok IDs. `videoUrl` is unknown for each row. Do not send these labels to the Actor. A real `languageCode` may be a regional value such as `eng-US`. This fiction uses `en` because the declared study language is English. In the tables, unknown is the study value. In the R example, `NA` stores that same unknown. Do not store unknown as 0.
The declared code is still the explicit instruction to measure water.
V1 is English. It succeeded. The caption was validated. The text is "I measure the water before I pour it". That text is an explicit instruction to measure water. The code is 1.
V2 is English. It succeeded. The caption was validated. The text is "I pour water into the tray". It tells someone to pour. It does not tell someone to measure. The code is 0.
V3 has status `no_public_captions`. The text is empty. `languageCode` is unknown. Do not invent one. `caption_validated` is unknown, not no. The code is unknown. Empty text is not code 0. It is also not proof of silence.
V4 has status `language_unavailable`. The text is empty. `languageCode` is unknown. `caption_validated` is unknown. The code is unknown. This failure is not the same failure as V3. Keep the two reasons apart.
V5 is English. It succeeded. A person compared the caption with the audio. The caption missed the measurement phrase. Validation is not finished. `caption_validated` is unknown, not no. `study_eligible` is no. The code stays unknown. Success is not the same thing as a trusted caption. Do not turn this row into code 0.
A video enters the share only when `study_eligible` is yes. That decision is separate from the code. V1 and V2 are eligible because the caption succeeded, the text is non-empty, and a person validated it. V3 and V4 are not eligible because collection failed. V5 is not eligible because validation is not finished. `isBillable` would be true for V1, V2, and V5, because those transcript results succeeded. `isBillable` would be false for V3 and V4. V5 is billable and still not eligible. The billable flag does not decide the study count.
Video table:
| selected_video_key | videoId | videoUrl | languageCode | caption_status | caption_validated | study_eligible | exclusion_reason |
|---|---|---|---|---|---|---|---|
| V1 | video-v1 | unknown | en | succeeded | yes | yes | none |
| V2 | video-v2 | unknown | en | succeeded | yes | yes | none |
| V3 | video-v3 | unknown | unknown | no_public_captions | unknown | no | no public captions; empty text not coded |
| V4 | video-v4 | unknown | unknown | language_unavailable | unknown | no | requested language missing; empty text not coded |
| V5 | video-v5 | unknown | en | succeeded | unknown | no | audio review unfinished; missed measurement phrase |
Code table:
| selected_video_key | code | code_version | coder | decision_note | timestamp |
|---|---|---|---|---|---|
| V1 | 1 | v1 | coder-a | explicit instruction to measure water | example-only |
| V2 | 0 | v1 | coder-a | pour instruction only; measure instruction absent | example-only |
| V3 | unknown | v1 | coder-a | failed caption; code not observed | example-only |
| V4 | unknown | v1 | coder-a | failed caption; code not observed | example-only |
| V5 | unknown | v1 | coder-a | caption not validated; code not observed | example-only |
Segment table:
| selected_video_key | startSeconds | endSeconds | text | source_observation |
|---|---|---|---|---|
| V1 | 0.5 | 2.5 | I measure the water before I pour it | validated caption evidence for code 1 |
| V1 | unknown | unknown | unknown | second measurement segment; extra evidence only; times not set here |
| V2 | unknown | unknown | I pour water into the tray | validated caption evidence for code 0 |
| V5 | unknown | unknown | unknown | caption missed a spoken measurement phrase; words not set here |
V3 and V4 have no segment rows. Their result text is empty. Do not add a segment at 0 seconds. Zero would look like a real time. Missing time stays unknown.
The first V1 segment ends at 2.5 seconds and starts at 0.5 seconds. 2.5 minus 0.5 is 2.0 seconds. That length uses `endSeconds` and `startSeconds`. The second V1 segment also supports the measurement code. It does not create a second video. V1 remains one coded video. The counted unit is the video.
Eligible validated videos: 2. Videos with code 1: 1. 1 / 2 = 0.5, which is 50 percent. The selected ledger still has 5 videos. 1 / 5 = 0.2, which is 20 percent. Do not report 20 percent. V3, V4, and V5 were not verified as code 0. Unknown is not zero.
Outcome counts for the five selected videos: 2 validated and eligible, 2 failed, and 1 validation unfinished. The two failures have different statuses. One is `no_public_captions`. The other is `language_unavailable`.
Suppose you submitted these five inputs once. Suppose there were no duplicates. The expected account below is arithmetic from this fiction. It is not a live receipt. `inputsReceived` would be 5. `resultRows` would be 5. `billableTranscriptRows` would be 3. `nonBillableResultRows` would be 2. `duplicateVideosSkipped` would be 0. `statusCounts` would show `succeeded` 3, `no_public_captions` 1, and `language_unavailable` 1. Your real run must be checked against the account you actually receive.
This example shows that extra segments do not add videos. It also shows the eligible denominator. It does not show a real set of videos. It does not show a caption accuracy rate. It does not show an effect beyond these made-up rows.
A flat JSON shape for the known V1 segment is:
{
  "videoId": "video-v1",
  "segments": [
    {
      "startSeconds": 0.5,
      "endSeconds": 2.5,
      "text": "I measure the water before I pour it"
    }
  ]
}That object is fiction for the flatten step. After flattening, the segment table above is the coding copy. The video table remains the counting copy.
Sources & further reading
By Chronometrica · Updated
Back to top ↑