Collection setup
To get raw data, use a hosted data collection program called an Actor. The Reddit Comments scraper helps you pull public threads. Change the task preset to use one known thread URL. Set the maximum comments per post limit between 1 and 500, with a default of 100. For this starter task, use a cap of 3 rows. Input postUrls requires 1 to 50 known public threads, and maxCommentsPerPost is 1 to 500 per post, with preset 250 changed to 3 for the pilot.
Each comment row has exact field names: postId, commentId, parentId, depth, body, status, unavailableFields, and observedAt. Preserve exact names, not spaced aliases. Dataset status is only ok, deleted, or removed. A partial or failed run or input state is separate from row status.
Run output data includes commentsSaved, duplicatesSkipped, hiddenBranchesRemaining, completionReason, status, isComplete, and inputResults. Per-input fields include commentsFound, commentsSaved, status, and reason. Current pilot three body present IDs have parentId and depth null, hiddenBranchesRemaining null, and overall or input results are partial despite isComplete=true processing flag. This is not full context or classifier quality proof. If a matching parent is needed, use a manual authorized public check or keep context unknown. Never guess a neighboring row.
Defining targets and labels
Before you read any text, define your target set and label unit. One unit here is a comment plus target, not one comment or one person. Specify five labels using plain rules:
- Positive: Expressed approval.
- Negative: Expressed disapproval.
- Neutral: Stating facts without a stance.
- Mixed: Holding both positive and negative views.
- Uncertain: The target or stance is unclear.
A target is the specific person, product, policy, or action the words talk about.
Eight steps to analyze comments
- Define your question, target set, and label unit before reading.
- Preserve source rows and output data. Keep comment identity, text, status, and missing data. Make a working label table instead of writing guessed sentiment into original fields.
- Read the matching parent context when available. Find explicit target mentions and pronouns. If you cannot resolve a pronoun safely, keep the target and context uncertain. Treat sarcasm as a reason to review, not an automatic negative label.
- Split multi-target statements. One comment can praise speed and dislike a price change. Do not assign a universal preference.
- Save the comment ID, target, evidence passage, context source, label, and reason. Keep quoted words from others separate from the author's own stance. Do not label a question as a complaint without context.
- Have a second reader code a small common subset. Record raw agreement and note which rules caused disagreements. Do not claim high accuracy without a justified reference standard. Refine your rules and relabel affected cases.
- Report counts by comment-target units and unique comment IDs separately. Multi-target comments add more label rows than comments. Keep uncertain labels and unavailable bodies visible outside resolved denominators.
- Deliver a target-stance table, a codebook, and disagreement notes. This prepares an inspectable dataset. It does not give product priorities, representative opinions, or automated reply actions.
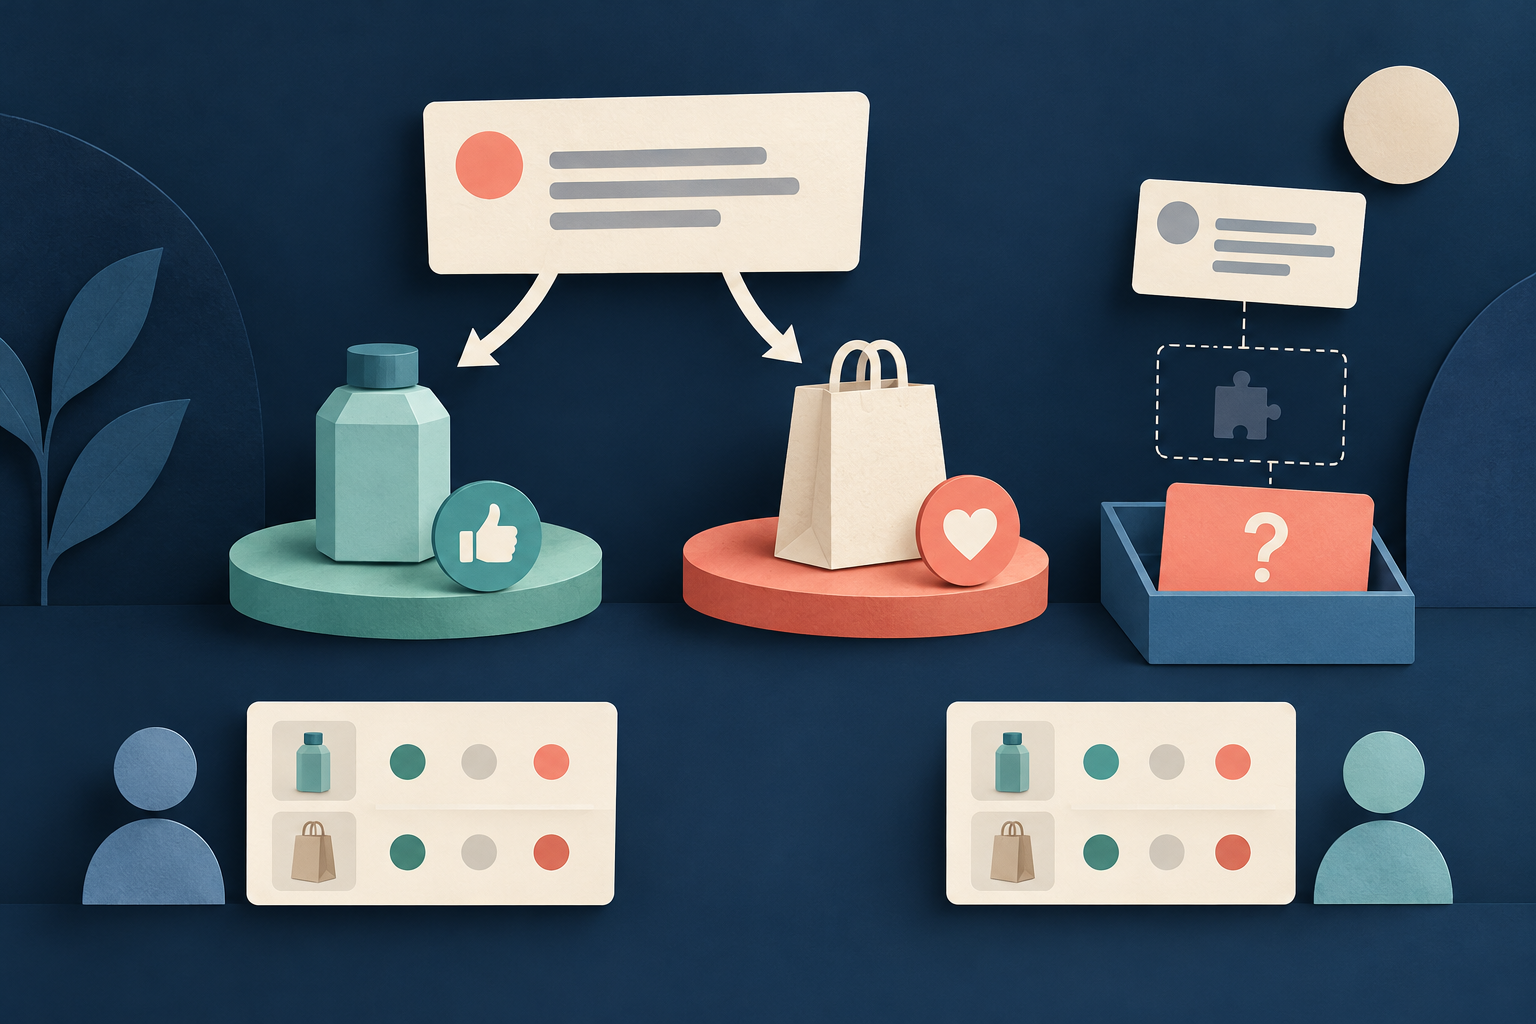
All text and IDs in this example are invented. Imagine parent context P asks about product A's new monthly price and product B's onboarding.
| commentID | matching context source | target | exact source passage | label | reason |
|---|---|---|---|---|---|
| C1 | Context P | Product A | "I still like A" | Positive | Expresses positive stance on product A |
| C1 | Context P | Price change (A) | "the new price is bad" | Negative | Expresses negative stance on price change |
| C2 | Context P | Onboarding (B) | "B was easy to learn" | Positive | Praise for onboarding ease |
| C2 | Context P | Speed (A) | "A was faster for our team" | Positive | Speed praise with team condition |
| C3 | Context P (confirmed) | Price increase | "Great, another price increase" | Negative | Sarcastic complaint confirmed by parent P |
| C4 | Unknown | Unknown | "Does it work offline?" | Uncertain | Unresolved target without parent context |
Note that C5 has a removed body status and sits outside the sentiment table as an availability record with no sentiment label.
Worked fictional example
Comment C1 says, "I still like A, but the new price is bad." This gives two units. Product A is positive. The price change for A is negative. Do not assign one universal negative stance to product A.
Comment C2 says, "B was easy to learn; A was faster for our team." This gives B onboarding as positive and A speed as positive, with a team condition. No overall winner is stated.
Comment C3 says, "Great, another price increase." This target price change is only counted if parent context P is confirmed. Label it negative or sarcasm after manual review, otherwise keep it uncertain.
Comment C4 says, "Does it work offline?" This has an unresolved pronoun without parent context. The target is unknown, so label it uncertain. Do not turn a question into negative offline feedback.
Comment C5 has its body removed, so it is not analyzed. Keep its availability position in the table.
With a confirmed parent for C3, the label table has six comment-target units from four body-available comments. That means two for C1, two for C2, one for C3, and one for C4.
The resolved units total five. Three are positive for C1 A, C2 B, and C2 A. Two are negative for C1 price and C3 price. One is uncertain for C4.
The positive score is 3 divided by 5, which equals 60 percent of resolved target units only. It is not 60 percent of commenters or community opinion. There are five observed positions and four available-body comments, with C5 removed outside sentiment.
Code agreement and limits
Two fictional coders label the five resolved units. Their initial agreement is 4 of 5, which equals 80 percent. Their difference on C3 concerns sarcasm and context. They review the actual parent condition and agree on a rule. This does not establish general 80 percent accuracy. If C3 parent is missing, it must remain uncertain. The resolved denominator falls to 4. Do not invent parent confirmation from neighboring rows.
The final artifact shows source pointers and each target separately, with C4 and C5 in an unknown and unavailable ledger. It does not provide topic frequency or feature priority tables. Real discussions follow similar community patterns. You can check a real sentiment project discussion for more context.
Sources & further reading
By Chronometrica · Updated
Back to top ↑