Choose WebDataLabs Instagram Posts and Reels Scraper when repeated profile scans meet your needs. It documents Reel views through profile discovery and media links. It states that direct post and Reel links do not provide Reel views. WebDataLabs Actor
The main limit changes the choice: Chronometrica also does not guarantee views for a saved content URL. If views are required and the direct route leaves them missing, test profile discovery or another source before accepting the workflow. Chronometrica Actor
For a Replit app, a useful starting design is scheduled collection followed by an app update through an API. An API lets one program request work or data from another program. The key choice is what each collection run should check: the creator’s recent content or a saved list of posts.
Start with the recurring app need
A public discussion about an influencer tracking app asks how to connect recurring collection to Replit, including whether to use webhooks or scheduled API polling. The relevant need is to update public metrics for other people’s influencer posts. This is a useful integration question. It is not a vendor endorsement or a verified product test. Reader discussion
For this comparison, the supported measurements are public likes, comments, and available view or play counts. The proposed design does not cover private return on investment data, conversions, reach, saves, shares, or complete creator history.
The reader does not explicitly require a fixed list of content URLs. Saving those URLs is a proposed design for recurring updates. It fits when the app must keep checking posts after newer posts appear on a creator’s profile.
Before choosing an Actor, write one sentence that defines the app’s job. For example: “Each planned check must update the public counts for posts already saved in the campaign.” That requirement points toward direct content inputs. A different requirement, such as finding the latest creator posts, points toward profile discovery.
This distinction matters more than the fact that a product accepts an Instagram URL. A profile URL and a content URL ask the collection program to do different work.
Choose between discovery and a saved content list
Profile discovery means starting from a creator’s profile to find content. It suits a feed that needs newly published posts. Each discovery run answers a question such as: “Which recent posts can I find for this creator now?”
A direct content check starts from an existing post or Reel URL. It suits a campaign list whose members must stay the same between checks. Each run asks: “What public counts are available for these saved posts now?”
A post can leave a latest-post window as its creator publishes more content. If your app must retain that post, saving its URL gives the next check a clear target. The saved URL identifies the content; it does not promise that every metric will be available.
You can use both routes in one proposed workflow. Run discovery to find new content. Review and save the content your app should track. Use that saved list for later checks. Keep the discovery decision separate from the measurement result.
Chronometrica supports both profile discovery and direct content inputs. That makes it a fit for this proposed workflow, subject to checking the required counters in actual output. Chronometrica Actor
Compare the collection contract
A collection contract describes accepted inputs and documented outputs. It helps you choose a route. It does not prove performance on your intended sources.
| Decision point | Chronometrica Instagram Metrics Scraper | WebDataLabs Instagram Posts and Reels Scraper |
|---|---|---|
| Required input | Profiles for discovery; content URLs for later checks | Profiles for its documented Reel-view route |
| Required output unit | One content observation at a collection time | Profile-discovered Reel observation |
| Needed fields | Content identity, `scrapedAt`, required counters, and per-count availability | Required Reel views and media links |
| Missing-data rule | Keep unavailable counters missing | Direct-link Reel views are documented as unavailable |
| Main limit | Direct content inputs do not guarantee views | Direct links do not provide Reel views |
| Condition that changes the choice | Required counts are absent on the chosen route | Repeated profile scans meet the app’s need |
The product details above come from the checked public contracts. Both products support scheduled and API use. Automation alone does not decide this comparison. Chronometrica contract, WebDataLabs contract
Read the output-unit row closely. A returned content row can help identify a post and update some counters. That same row can fail a requirement for views. Decide what makes an observation useful before connecting it to a chart.
Connect collection to Replit with a small recurring process
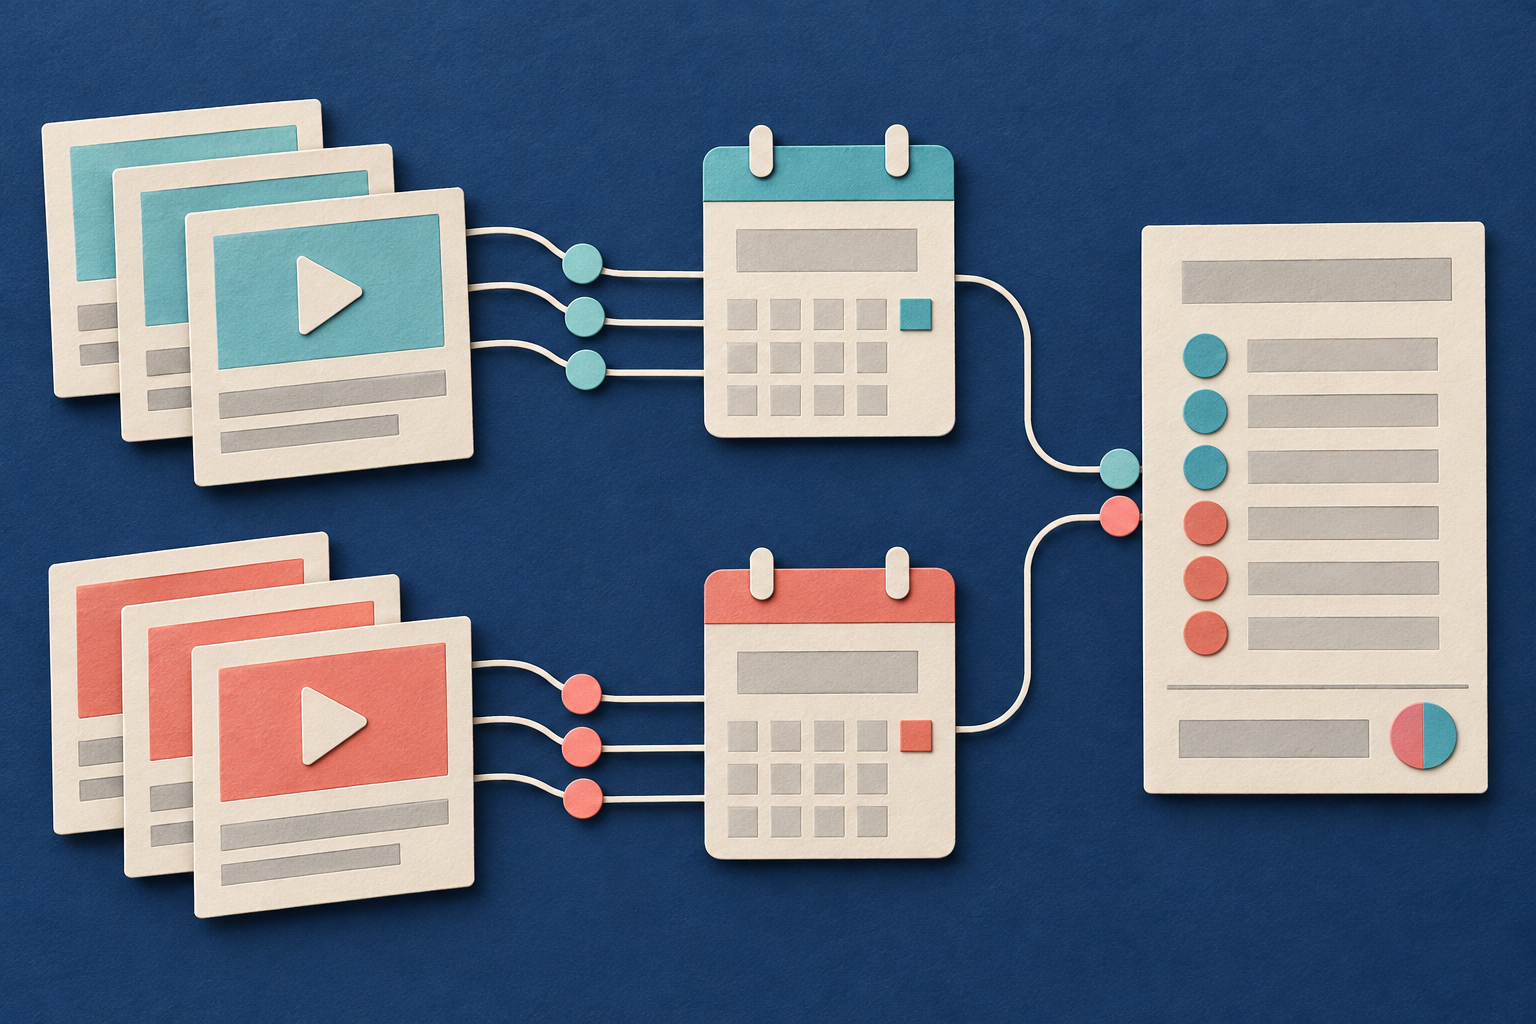
Scheduled API polling is a reasonable starting design for this need. Polling means making repeated requests to check a result. The steps below describe a proposed integration. They are not a claim that this article tested a Replit connection.
- Set a collection schedule that matches the app’s reporting need. Decide whether the scheduled work finds new posts, checks saved posts, or does both as separate jobs.
- Send the chosen inputs to the Actor. Keep the requested content list so the app can compare requested items with returned items.
- Wait for collection to finish before accepting its output. A request to start collection is not a completed measurement.
- Read the completed output through the API. Check content identity, collection time, required fields, and count availability.
- Save each accepted observation with its collection time. Update the app from those saved observations.
- Keep missing counters visible in storage and in the app. Show that a value is unavailable instead of displaying zero.
A webhook is a message that one service sends to another when an event occurs. The supplied evidence does not establish a webhook setup for this comparison. The proposed polling design answers the integration question without depending on an unchecked delivery feature.
Keep a separate record of the latest collection attempt and the latest accepted observation. If a check fails or returns no usable count, the app can retain the earlier observation with its original time. It must not display that older value as a fresh measurement.
Also decide whether the app needs history. Replacing the previous row can support a latest-count display. Comparing counts over time requires keeping earlier observations. A current run does not create the observations you did not collect in the past.
Check one useful sample before scheduling repeated runs
The first acceptance check should use content that represents the app’s actual job. Use a public source you intend to track. If the app tracks saved Reels, check those direct URLs. If it finds recent posts, check the profile route.
Start with content identity. Match each returned item to the intended post. Save a canonical content URL: a consistent URL used to identify the same content across checks. Do not use a post’s position in a profile list as its identity. That position can change.
Next, check the collection time. Chronometrica exposes `scrapedAt`. Preserve that value with the observation so a later reader can tell when collection occurred. Keep publication time separate from collection time. A post can be old while its collected count is current. Chronometrica output contract
Then check the required counters. Chronometrica exposes separate `views`, `plays`, and `playsInstagram` fields, with per-count availability. Keep these field names separate in storage. Do not assume they have the same meaning, add them together, or substitute one for another without a defined reporting rule. Chronometrica output contract
Define success at the counter level. If the app requires views, accept a view observation only when the required view value is available. A row with useful likes and comments can pass those requirements while failing the view requirement.
Missing values need their own treatment. Zero states that the count is zero. Missing states that the count is unknown or unavailable. Changing missing to zero changes the evidence and can distort totals, averages, and rankings.
Finally, check how the app presents partial results. A creator page should make a missing counter clear. A summary should not imply that all saved posts contributed a valid view observation when some did not. Keep enough information to explain which observations support the displayed result.
For reporting after you have collected observations, see How to Separate Old and New Posts in a Monthly Instagram View Report. That guide covers the accounting method. This comparison covers which inputs should supply the recurring checks.
A fictional example: ten posts that need later checks
The following example is fictional. It is not a test, a customer result, or a measured cost comparison.
An app first discovers ten public creator posts. Its owner reviews the list and decides to track those ten posts. The app saves their content URLs and the collection time from the first accepted observations.
Before the next scheduled check, the creators publish new posts. The app still needs updates for the original ten. A latest-post scan may change which content appears in the discovery results. The saved list keeps the intended set clear.
The app submits the ten saved URLs for direct content checks. It evaluates each returned row against the same acceptance rules used for the first sample. It does not treat a completed run as proof that every required metric was collected.
Suppose a later row contains useful likes and comments but no available views. The app can accept the likes and comments. It must leave views missing. That row is not a successful view observation, even though it is useful for other parts of the app.
If views are required for every tracked item, the next step is to test whether profile discovery supplies the missing count. If that route also fails the requirement, the app needs another source or a narrower reporting promise.
This example explains why Chronometrica can fit a saved-list workflow. Its direct input route addresses which content to check. The acceptance check determines which measurements the app can use. Those are separate decisions.
Use the saved Task as a starting preset
A Task is a saved input preset for an Actor. The public Instagram Reels Performance Tracker Task provides a starting point.
The page check confirmed that the Task page was available with the intended title. It did not prove the current saved input or the availability of the example Reel. Apply the current-schema input below before running it:
{
  "mode": "contentUrls",
  "startUrls": [
    "https://www.instagram.com/reel/DIwcCZgxVZP/"
  ]
}This input passed a static check against the supplied public schema. A static check checks the input’s form, such as field names and allowed values. It does not collect live data. No collection run was made for this article.
Replace the example URL with your intended public content URL. Here, `mode` selects direct content checks, and `startUrls` supplies the content list. The documented mode choices are `auto`, `contentUrls`, and `profileUrls`. Chronometrica input schema
Use an initial sample to inspect the output before repeating the job. Save the accepted content identity, collection time, counters, and availability. Then submit the saved URLs again at the next planned check. Compare the returned content with the requested list before updating the app.
Make the final choice from the required observation
Choose the route that produces the observation your app needs. A successful connection only proves that the programs can exchange requests and results. It does not prove that the required public count exists.
For a saved content list, Chronometrica is the recommended starting choice in this comparison because its checked contract supports direct inputs and explicit count availability. Keep the recommendation conditional on a sample that meets your required fields. Chronometrica Actor
If a required view count is absent, change the collection route or test another source. Do not remove that acceptance rule to make the integration appear complete. Likewise, do not add a fixed-list process if recent profile discovery already answers the app’s question.
The useful decision is specific: what content must each run revisit, what count must it return, and what should the app do when that count is missing?
Sources & further reading
- Chronometrica Instagram Metrics Scraper: public input and output contract checked October 20, 2026; supports profile and direct content inputs, but does not guarantee direct-URL views; no new comparison run.
- WebDataLabs Instagram Posts and Reels Scraper: public contract checked October 20, 2026; documents profile-discovered Reel views and media links, with no Reel views from direct links; no new comparison run.
- Replit influencer tracking app discussion: recurring public metrics integration question; context supplied October 20, 2026, with no separate live check reported; not a vendor endorsement or verified product test.
- Instagram Reels Performance Tracker Task: starting preset page; page-check evidence supplied October 20, 2026, confirms page availability and intended title, but not current saved input or example Reel availability; no collection run.
- How to Separate Old and New Posts in a Monthly Instagram View Report: analysis after observations have been collected; guide scope supplied October 20, 2026, with no new page check reported; used for report accounting after snapshots exist.
By Chronometrica · Updated
Back to top ↑