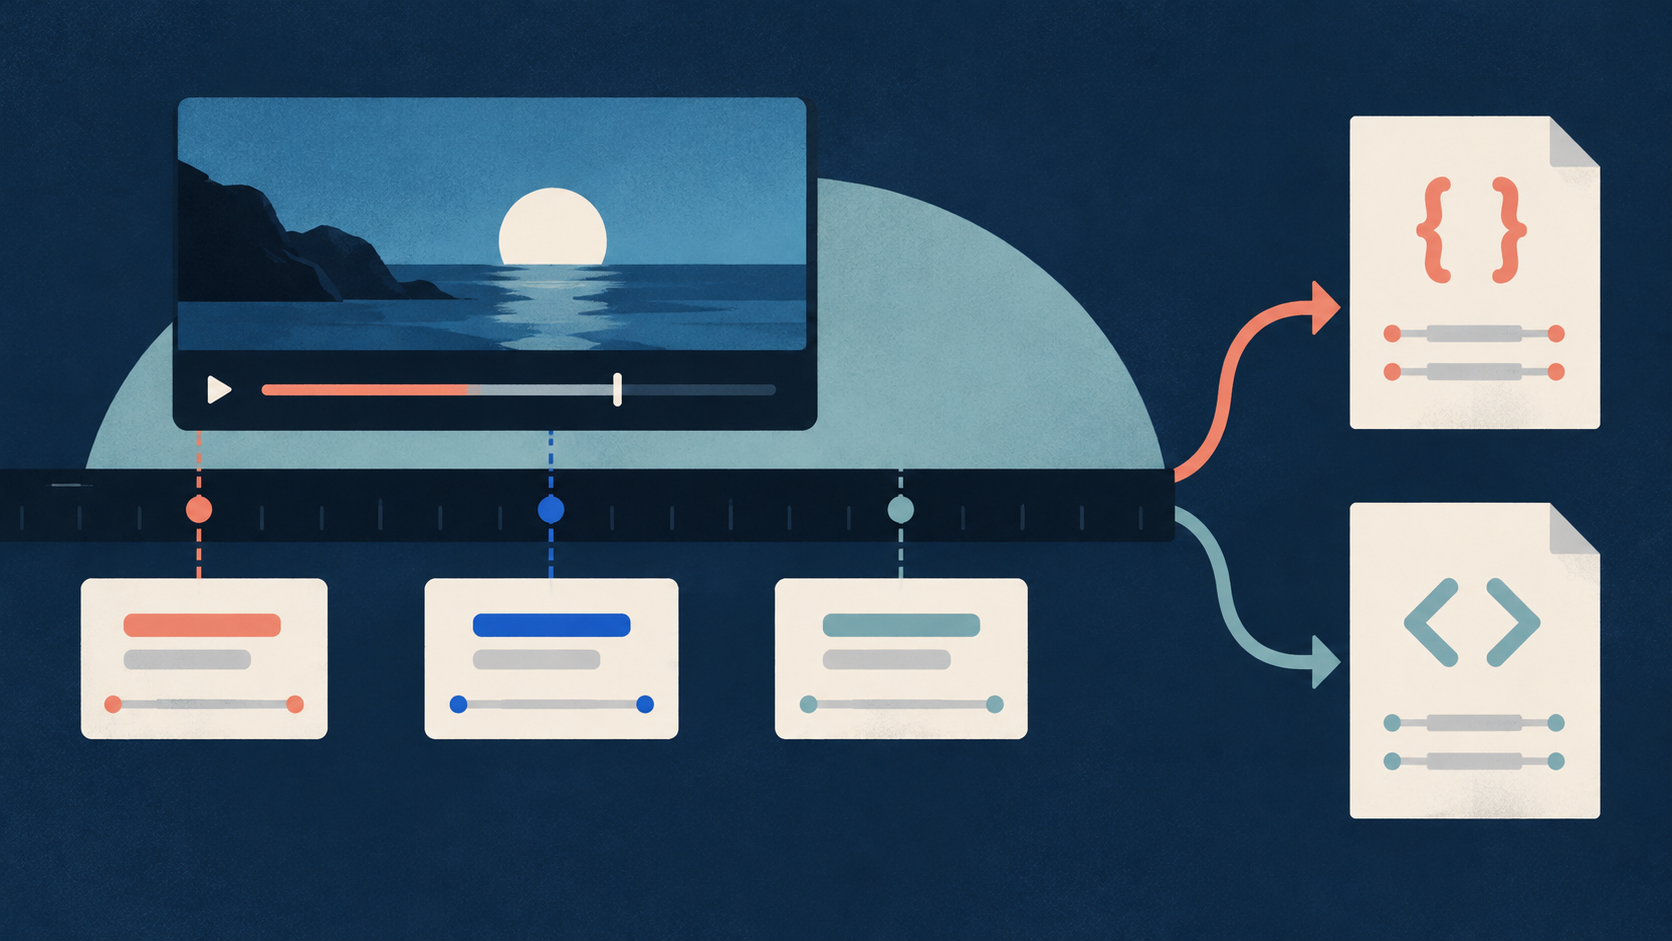
SRT and VTT are subtitle text formats. Each subtitle cue contains words and the start and end times for those words. A cue is one subtitle entry. The useful result is subtitle text you can save and open in your intended player or editor.
Chronometrica publishes this comparison. The product details below come from public documentation checked on October 20, 2026. This is an output comparison, with no measured claim about accuracy, speed, or price.
Choose who should prepare the subtitle text
A copied YouTube transcript can contain time labels without being a usable subtitle file. A reader raised this problem in a YouTube community question. The reader had transcript text, but the copied times did not match SRT syntax.
That problem has two parts. First, obtain the caption words and their times. Then arrange them in the subtitle format your editor accepts. The second part is the rendering step: turn timed segments into subtitle text.
For a person with public video URLs and no subtitle formatter, Chronometrica is a strong fit. Its optional `srt` and `vtt` fields contain rendered subtitle text. You can save the requested field and check it in your editor. The Actor returns text fields; choosing a format does not automatically create a downloaded subtitle file. An Actor is a hosted data collection program. (Chronometrica documentation)
The main condition that changes this choice is control over the conversion. You might already have rules for joining short segments, placing line breaks, or preparing captions for a specific editing workflow. Those are your editing rules. They are not product settings established by this comparison.
| Decision point | Chronometrica | Pinto Studio |
|---|---|---|
| Checked output | Optional rendered `srt` and `vtt` text | A `data` array with `start`, `dur`, and `text` |
| Work before a subtitle check | Save the requested text field | Convert segments to the required format |
| Best fit here | You want the rendering supplied | You control the conversion |
The table describes the documented output shapes. (Chronometrica, Pinto Studio)
Check the caption requirement before choosing a format
Chronometrica extracts existing public captions. It does not create speech-to-text output when captions are absent. Speech-to-text means generating written words from recorded speech. If your task requires text from a video with no available captions, choosing SRT instead of VTT will not solve that problem. (Chronometrica documentation)
Write down the source video URL, required caption language, and target subtitle format before you run the Actor. These three details define what success means. A readable subtitle in the wrong language does not meet a request for English subtitles.
Chronometrica tries `preferredLanguages` in the order you supply them. If none of the requested languages matches, it reports a typed failure instead of substituting another language. A typed failure identifies the kind of problem. Add another language only if you will accept it as a result. (Chronometrica input, output contract)
Keep extraction separate from translation. If you require a different language, decide how you will obtain and review that text. The guide to reviewing YouTube translation meaning explains that separate review need.
For this comparison, success means obtaining the requested existing track, preparing the required subtitle format, and checking that result against the video. It does not mean that every public URL must produce captions.
Request SRT or VTT explicitly in Chronometrica
Chronometrica accepts `json`, `text`, `srt`, `vtt`, and `llm` in `outputFormats`. Its defaults are `json` and `text`. You must therefore request `srt` or `vtt` explicitly when you need those fields. (Current input schema)
The public YouTube subtitles SRT/VTT Task is a starting preset. A Task is a saved input preset. Check the actual input before you run it, because a saved preset can change.
The following input was checked against the public schema. It was not run. The example URL comes from the public schema example, and its current caption availability is unknown. Replace it with a public video relevant to your subtitle task.
{
  "startUrls": [
    "https://www.youtube.com/watch?v=dQw4w9WgXcQ"
  ],
  "preferredLanguages": [
    "en"
  ],
  "outputFormats": [
    "json",
    "srt",
    "vtt"
  ],
  "includeFailedInputDetails": true
}This input requests English and both subtitle renderings. It also requests structured output so you can compare the subtitle text with the timed segments. Keep both formats only if you need to check both. For a task that needs one format, request that format explicitly.
A successful video produces one row with video identity, caption language, and timed segments. The optional `srt` and `vtt` fields hold the requested subtitle text. Failures go to `OUTPUT`, separate from the successful dataset. The `includeFailedInputDetails` setting keeps input-level failure details there. (Chronometrica output, input schema)
Read both places. The successful dataset shows what you obtained. `OUTPUT` explains failed inputs. Do not turn a failed lookup into an empty subtitle file. That would hide the difference between a successful extraction and missing source text.
Use segment output when you own the conversion
Pinto Studio documents one `videoUrl` and `targetLanguage` per run. Its published output example represents `start` and `dur` as numeric strings in seconds. These values can be converted into subtitle times. (Pinto Studio input, output example)
For a conversion process you control, read those values as numbers before adding them. The end time is the start time plus the duration. Keep the units consistent, then write the required subtitle syntax.
This extra step can be useful when your existing process already applies editing rules. For example, your editor might require a review of short cues before export. Your process can keep the original segments, apply your chosen changes, and record what changed.
If you do not need that control, writing and maintaining a formatter adds work to the subtitle task. A supplied rendering lets you begin with the save-and-check stage. You still need to confirm that the file opens and that its cues fit the video.
For complete conversion instructions, use the YouTube subtitle conversion guide. The decision here is whether your workflow needs that conversion step under your control.
Check the difference with a fictional example
This entire example is fictional. It checks subtitle formatting and arithmetic. It is not a live Actor result or evidence about either product’s caption accuracy.
Suppose you have two invented segments:
| Segment | Text | Start | Duration | End |
|---|---|---|---|---|
| A | Open the editor. | 1.25 seconds | 2.50 seconds | 3.75 seconds |
| B | Check the subtitle. | 4.00 seconds | 1.20 seconds | 5.20 seconds |
Segment A ends at `1.25 + 2.50 = 3.75` seconds. Segment B ends at `4.00 + 1.20 = 5.20` seconds. The gap between them is `4.00 - 3.75 = 0.25` seconds. Both durations are positive, and the cues do not overlap.
The SRT rendering is:
1
00:00:01,250 --> 00:00:03,750
Open the editor.

2
00:00:04,000 --> 00:00:05,200
Check the subtitle.The equivalent VTT rendering is:
WEBVTT

00:00:01.250 --> 00:00:03.750
Open the editor.

00:00:04.000 --> 00:00:05.200
Check the subtitle.The SRT times use commas before milliseconds. The VTT times use decimal points, and the VTT text begins with `WEBVTT`. Both renderings preserve the same two cues and their times.
If you receive a supplied rendering, compare it with the segments. Confirm that it contains two cues, two positive durations, and the same quarter-second gap. If those checks pass, you can save the text without writing the conversion yourself.
If your own process starts from segments, it must calculate the end times and write the syntax. Custom merging or line breaks add another editing decision. Preserve the original text and times so you can review those changes later.
Use a small subtitle acceptance method
Use one relevant public video to establish a working process. Set clear success checks before you prepare more subtitles.
- Declare the required result. Record the video URL, caption language, and target format. Name the player or editor that will receive the subtitle. This keeps the acceptance check tied to the place where the file must work.
- Check the current input. Request the required subtitle format explicitly. If you use the input above, replace the example URL. Review the language list in order, and include only languages you can accept.
- Read success and failure information together. Confirm that the successful row belongs to the intended video and caption language. Review `OUTPUT` for failures. Record missing captions or an unavailable requested language as unresolved work. Preserve unknown values as unknown.
- Prepare the subtitle file. For supplied rendering, save the contents of the `srt` field as an `.srt` file or the `vtt` field as a `.vtt` file. Save the subtitle text itself. For segment output, calculate start and end times using consistent units before writing the format.
- Check the cues. Confirm cue order, positive durations, and time syntax. Inspect gaps and overlaps. A gap can be a period without speech. An overlap needs review against the source. Keep the source URL and caption language with the saved file.
- Open and listen. Load the file in the intended player or editor. Check selected cue starts and ends against the video. Compare the words with the speech. A file that opens correctly can still contain poor caption words or poor timing.
- Record the decision. Mark the subtitle as accepted or unresolved. State what remains to be checked. If captions are unavailable, choose a separate speech-to-text process only when your task permits newly generated text.
The checks answer different questions. Format checks establish whether the subtitle text has the required structure. Playback checks establish whether selected cues work with the video. Word checks establish whether the caption text is suitable for your use.
Keep those results separate. “The file opens” is a useful result, but it does not establish that every word or cue is correct. A short acceptance record lets another person see which checks you completed.
Keep the source details with the subtitle
A useful subtitle handoff includes the source video identity, caption language, subtitle text or saved file, and a short cue check. Without those details, the next person must work out where the file came from and what you reviewed.
Use a short record with the source URL, requested format, returned caption language, saved file name, and review status. Add a plain sentence about the cue check. For example, state which boundaries you listened to and whether they need changes. Keep the original output available when you edit the subtitle.
Do not claim complete review after checking one cue. State the check you performed. If a language value or source detail is missing, leave it marked as unknown until you can establish it.
This record also helps you decide whether the supplied rendering meets your needs. If your remaining work is ordinary subtitle review, supplied SRT or VTT text is a useful starting point. If you must apply repeatable editing rules before every handoff, control over the conversion may matter more.
Sources & further reading
By Chronometrica · Updated
Back to top ↑