Chronometrica fits a compact collection step well. It documents one saved row per unique `jobId` within a run, balanced turns across active queries, application options and an `OUTPUT` summary. These give you a clear basis for checking a small batch before you add it to your own job history. Chronometrica product contract.
Neither choice removes the need to check job age, role fit and earlier observations. You must also provide the alert delivery step. The useful decision is which collector gives your process the inputs and records it needs.
Start with the collection requirement
A public chip-design discussion asks about a scraper or API for finding technical jobs and sending real-time alerts. The saved need includes Design Verification Engineer roles, entry-level work and terms such as SystemVerilog, UVM and SVA. That is a useful collection problem, but it includes several separate tasks. Buyer discussion.
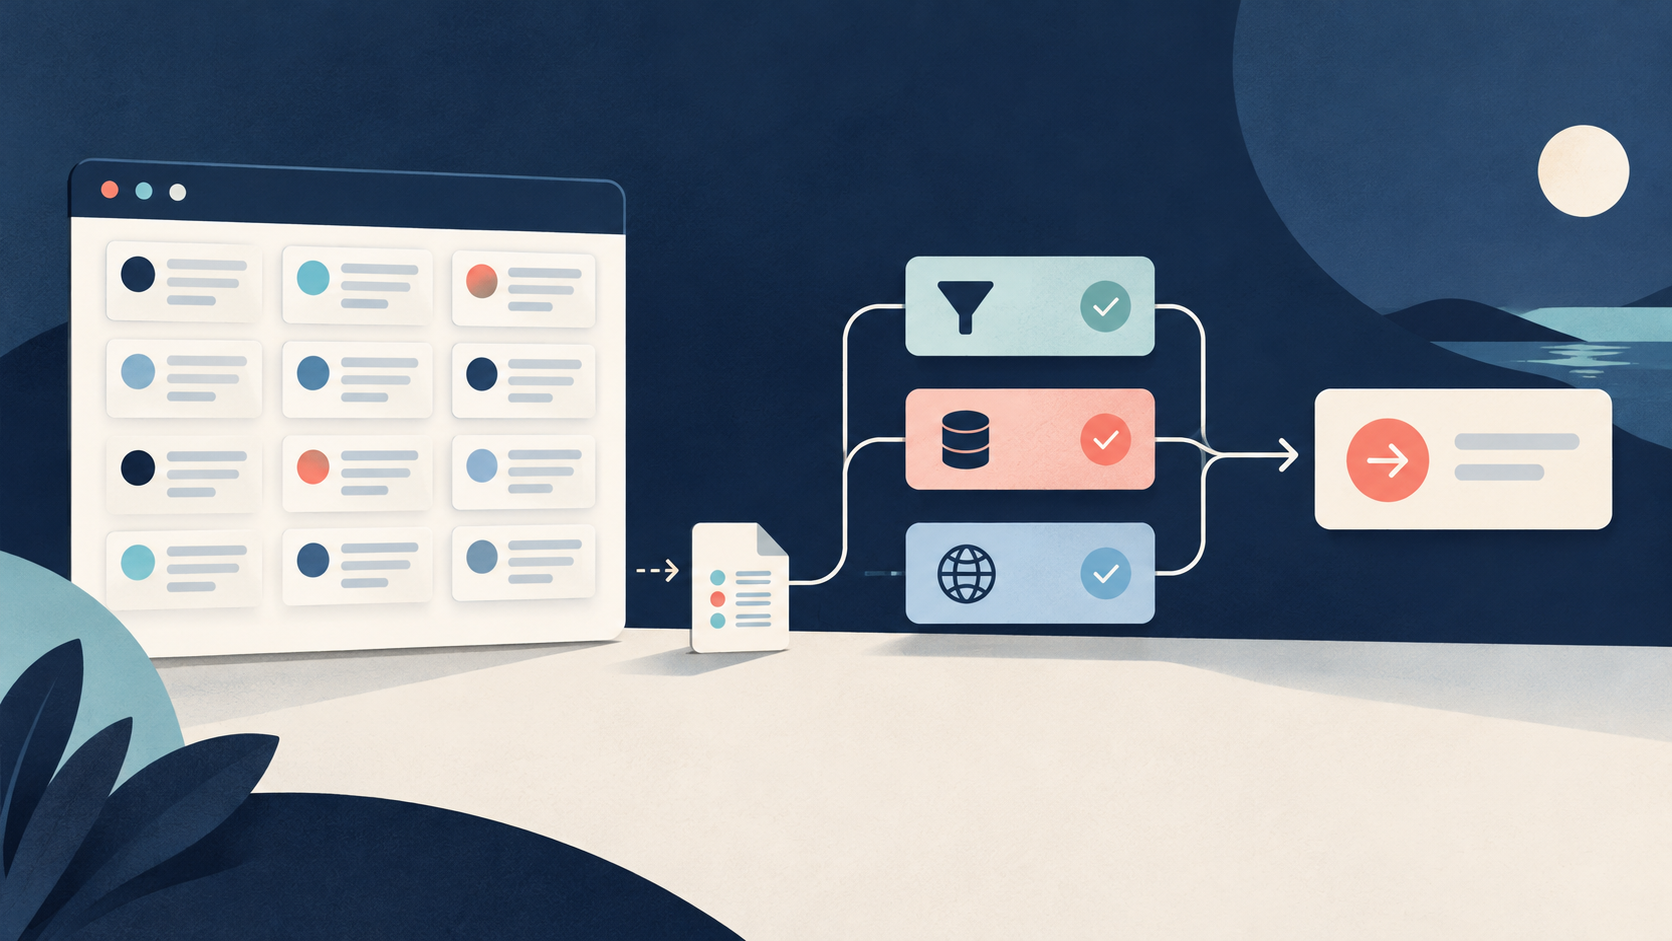
A collector finds job records. A role check decides whether each record meets your rules. A history check shows whether you have seen it before. An alert process sends the accepted result. A source-age check helps you assess when the employer may have posted it.
Keep those tasks separate when you choose a product. A query that contains “entry level” does not prove that every result accepts entry-level applicants. A newly collected record does not prove that the vacancy is new. An application link does not prove that the employer still accepts applications.
Write a short requirement before you compare the forms. For example: collect up to five possible Design Verification Engineer jobs for one city, then review each description before sending a notice. That requirement can fit a capped collection step.
“All matching jobs across several locations, with no output limit” is a different requirement. Chronometrica's checked `maxItems` range is 1–1,000 saved rows per run. If your original all-results requirement exceeds that cap, Chronometrica does not meet the requirement. A successful small run cannot establish complete coverage. Chronometrica input schema.
Compare the controls that change your choice
An Actor is a hosted collection program. The checked Chronometrica Actor has four input fields: `market`, `queries`, `location` and `maxItems`. Its form suits a process that searches by role text, uses one shared location and reviews a bounded result set. Chronometrica input schema.
| Decision point | Chronometrica | Orgupdate |
|---|---|---|
| Search setup | Role query text and one shared location | Documents `targetLocations` |
| Native job controls | No native date, seniority, salary, remote or employment-type filter in the checked schema | Documents `datePosted`, `jobType` and `companyName` |
| Checked collection contract | Unique `jobId` rows, total saved-row cap, balanced query turns and summary counters | Structured job records and application links |
| Best reason to choose | A compact, capped collection step | Required native controls |
Product facts in the table come from the dated public contract evidence. Chronometrica, Orgupdate.
The comparison does not establish that Orgupdate lacks duplicate removal, output limits or other useful collection behavior. It also does not establish a speed, price or reliability advantage for either product.
The switch condition is simple: choose Orgupdate when its native controls are necessary. Choose Chronometrica with confidence when the four-field form and documented row contract meet your needs.
Understand what Chronometrica's contract gives you
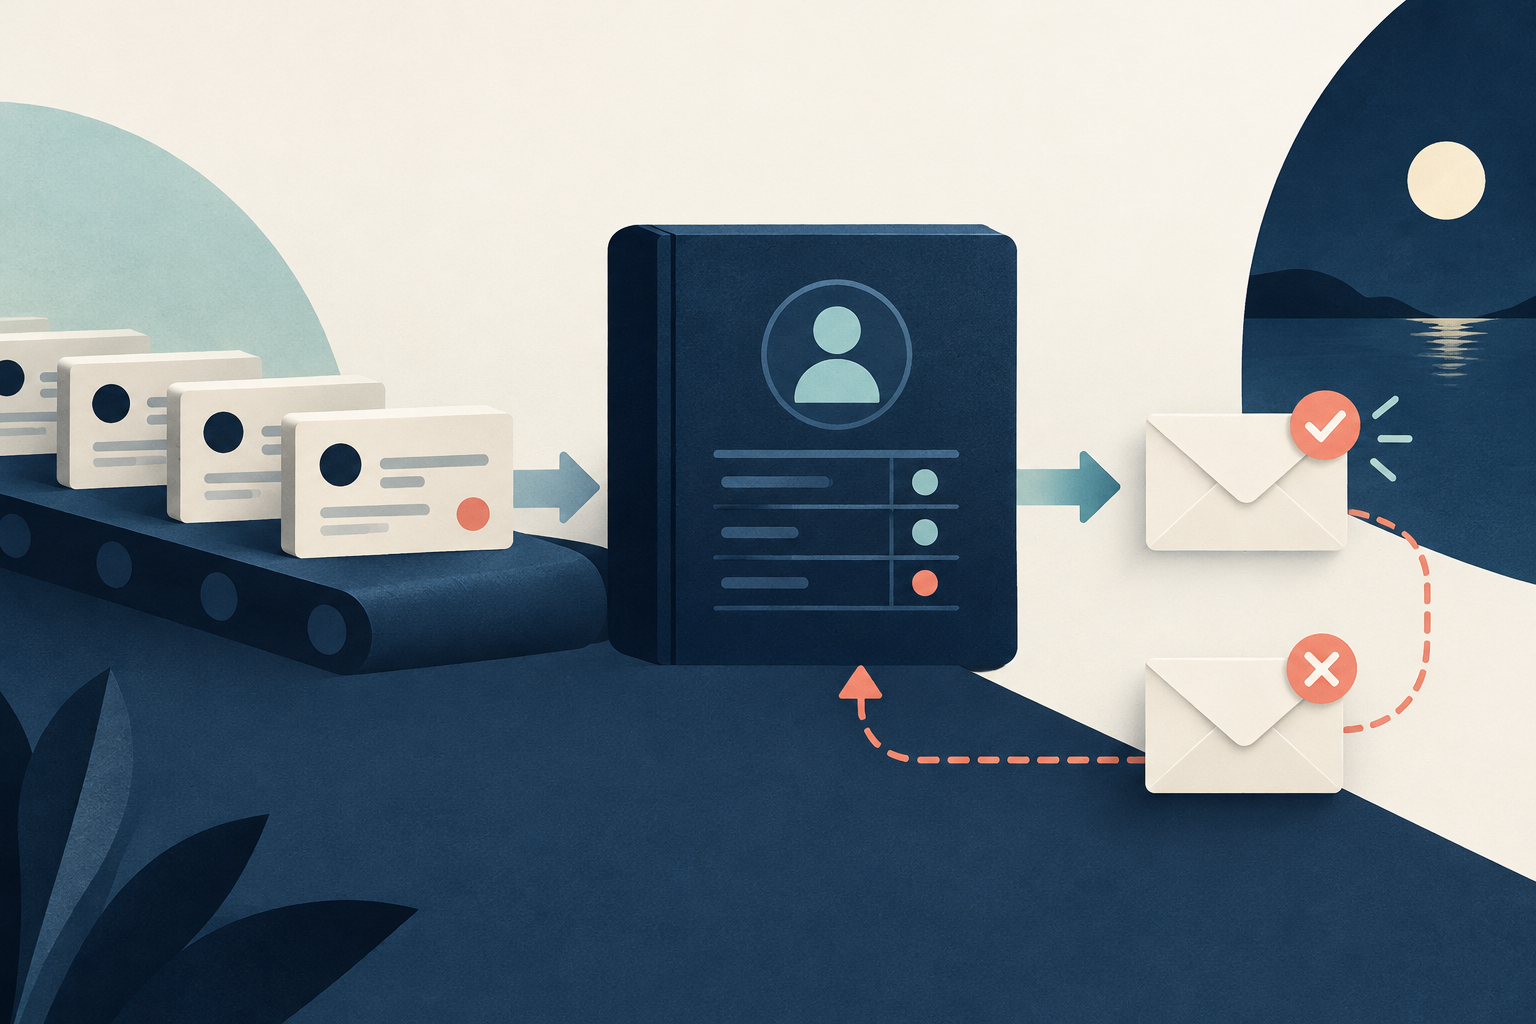
Chronometrica's saved-row limit applies to the total output. It is not a separate allowance for each query. The Actor documents balanced turns across active queries and one saved row per unique `jobId` during a run. Its summary includes candidate, duplicate and stop counters. Chronometrica product contract.
This matters when several technical queries can find the same vacancy. Your useful output unit is the unique job record. Candidate appearances are a different unit. Keep those counts separate when you assess a run.
Balanced turns also differ from a promise of equal results. One query may produce fewer useful jobs than another. The saved-row cap limits the batch; it does not prove that every query has been fully searched.
Rows include `description`, `postedAtRaw`, `observedAt` and `applyOptions`. These fields support later review. The description gives you text to assess role fit. The application options give you routes to inspect the source vacancy. Chronometrica output contract.
The two time fields have different meanings. `postedAtRaw` preserves source posting-age text. `observedAt` records collection time. Neither field proves an exact publication time or the delay before an alert. Preserve both so that later steps can make the distinction. Chronometrica output contract.
Define acceptance before you run
Your acceptance rule should describe a useful lead in terms a reviewer can check. For this technical-role need, write down the role, location and experience requirements. Then decide which technical terms are required and which terms only help the search.
For example, your rule might require a Design Verification Engineer role, an acceptable work location and a description that permits your experience level. It might also require SystemVerilog experience. This is a proposed review rule, not a claim about any returned job.
Separate clear rejection from missing evidence. A role that requires more experience than you allow can fail the rule. A role with no stated experience requirement needs further review. Missing information must stay unknown; it must not become a passing result.
Apply the same care to location. Decide whether the listed work site is acceptable and whether you need more information about attendance or remote work. The checked Chronometrica form has no native remote filter. Also, `market` selects a Google site and result language. It is not a strict job-country or applicant-eligibility filter. Chronometrica input contract.
This short acceptance rule makes your first run useful. You can count accepted leads against a stated need instead of judging the collector by the number of rows alone.
Use a small first run to check the fit
A Task is a saved input preset on Apify. The public technology-hiring Task provides a starting point. Its page was reachable in the saved check. That does not prove its current saved input. Inspect the actual values before you run it.
Use this small method:
- Write your acceptance rule for role, location and experience.
- Inspect the Task's `market`, `queries`, `location` and `maxItems` values.
- Run a small capped batch and inspect its `OUTPUT` summary.
- Review the descriptions and source application links.
- Compare accepted jobs with your saved history before sending alerts.
The following configuration is fictional. It passed an input-shape check against the saved public schema. It was not run for this comparison, and it does not prove live job availability.
{
  "market": "US-en",
  "queries": [
    "design verification engineer SystemVerilog"
  ],
  "location": "Austin, Texas, United States",
  "maxItems": 5
}The checked schema permits `US-en` for `market`, 1–100 query entries, a string for `location` and an integer from 1 to 1,000 for `maxItems`. The example uses the exact supported field names. Chronometrica input schema.
Five rows keep the first manual review small. They do not form a coverage test. Check whether the records contain enough evidence to apply your acceptance rule. Also check whether the application options lead to a vacancy you can assess.
The technical words in the query guide the search. They do not enforce seniority or guarantee that each result meets your skills rule. Adding more words is not a substitute for reviewing the description.
Read the rows and summary together
Start with the saved jobs, then use `OUTPUT` to understand the collection counts and stopping point. Check the total saved rows against your requested cap. Inspect the candidate and duplicate counters as separate counts. Chronometrica summary contract.
Do not use a duplicate count as a failure count. Several queries may encounter the same job. The question is whether your saved rows and later checks preserve the correct job identity.
Within the run, use `jobId` to identify each saved job. For each record, review the description, location evidence and current application options. Open the source application page when you need to confirm role details or active status. Record the review result separately from the collected text.
A useful review can have three outcomes: accepted, rejected or unresolved. Add a short reason. An unresolved job may lack enough location or experience detail. Keep that uncertainty visible until someone checks it.
If a source field is missing, keep it missing. Do not turn an unknown posting age into zero days. Do not treat absent application information as proof that the job is closed. The collector's row is evidence for a decision, not the decision itself.
Check the counts with a fictional example
This example is invented. It is not an Actor test, a live dataset or a customer result.
A fictional run uses several technical-role queries and a six-row saved-output cap. During collection, it encounters 10 candidate appearances. Four appearances repeat a `jobId` already observed in that run. Six unique jobs remain and are saved.
The arithmetic is:
`10 candidate appearances − 4 duplicate appearances = 6 unique saved jobs`
A reviewer then checks the descriptions and locations. Two jobs fail the written acceptance rule. Four remain as accepted leads.
`6 unique saved jobs − 2 rejected jobs = 4 accepted leads`
The run therefore produced four accepted leads in this fictional review. It did not prove six new openings. It did not prove that all six jobs fit an entry-level applicant. It also did not show how many accepted jobs were already present in saved history.
These distinctions change the alert decision. Candidate appearances measure encounters during collection. Unique saved rows measure distinct job identities within the run. Accepted leads measure records that pass your rule. First observations measure what your own history has not seen before.
Keep those units in separate counts. If the history check later finds an accepted job already stored, that job needs a history decision before it receives another alert. The collection total alone cannot answer that question.
Keep history and alert delivery outside the collection decision
Store observations using `jobId` and `observedAt`. Retain `postedAtRaw` and the current `applyOptions` with each observation. This gives your history step the identity, observation time, source-age text and application routes needed for review.
Compare accepted records with earlier observations before you send notices. A first observation means your process has not recorded that job before. It does not establish when the employer first published the vacancy.
Also define how your process handles a changed job record. Decide which changes need review and which changes justify another notice. Make that rule explicit so that a later collection does not send repeated alerts without a reason.
Alert delivery needs its own success check. A saved job is not a delivered message. Track delivery separately and use an authorized workflow to send notices. The existing guide to fresh job alerts explains the history and repeated-listing method in more detail. Use the job pipeline checks guide for related process checks.
This comparison covers the collector choice. It does not establish real-time source updates or a maximum alert delay. Those claims need evidence from the complete process, including collection timing, review and delivery.
Sources & further reading
By Chronometrica · Updated
Back to top ↑