An Actor is a hosted collection program. Both products are Apify Actors. We publish Chronometrica, and we recommend it for the focused post-search need described here. This comparison uses product evidence captured on 20 October 2026. It does not report a new matched test, measured speed difference, or price advantage.
The buyer question is practical: how do you collect keyword matches across selected subreddits? A public Reddit question asks for tools for that need. It does not ask for a complete Reddit archive. It also does not establish that every returned match will be useful.
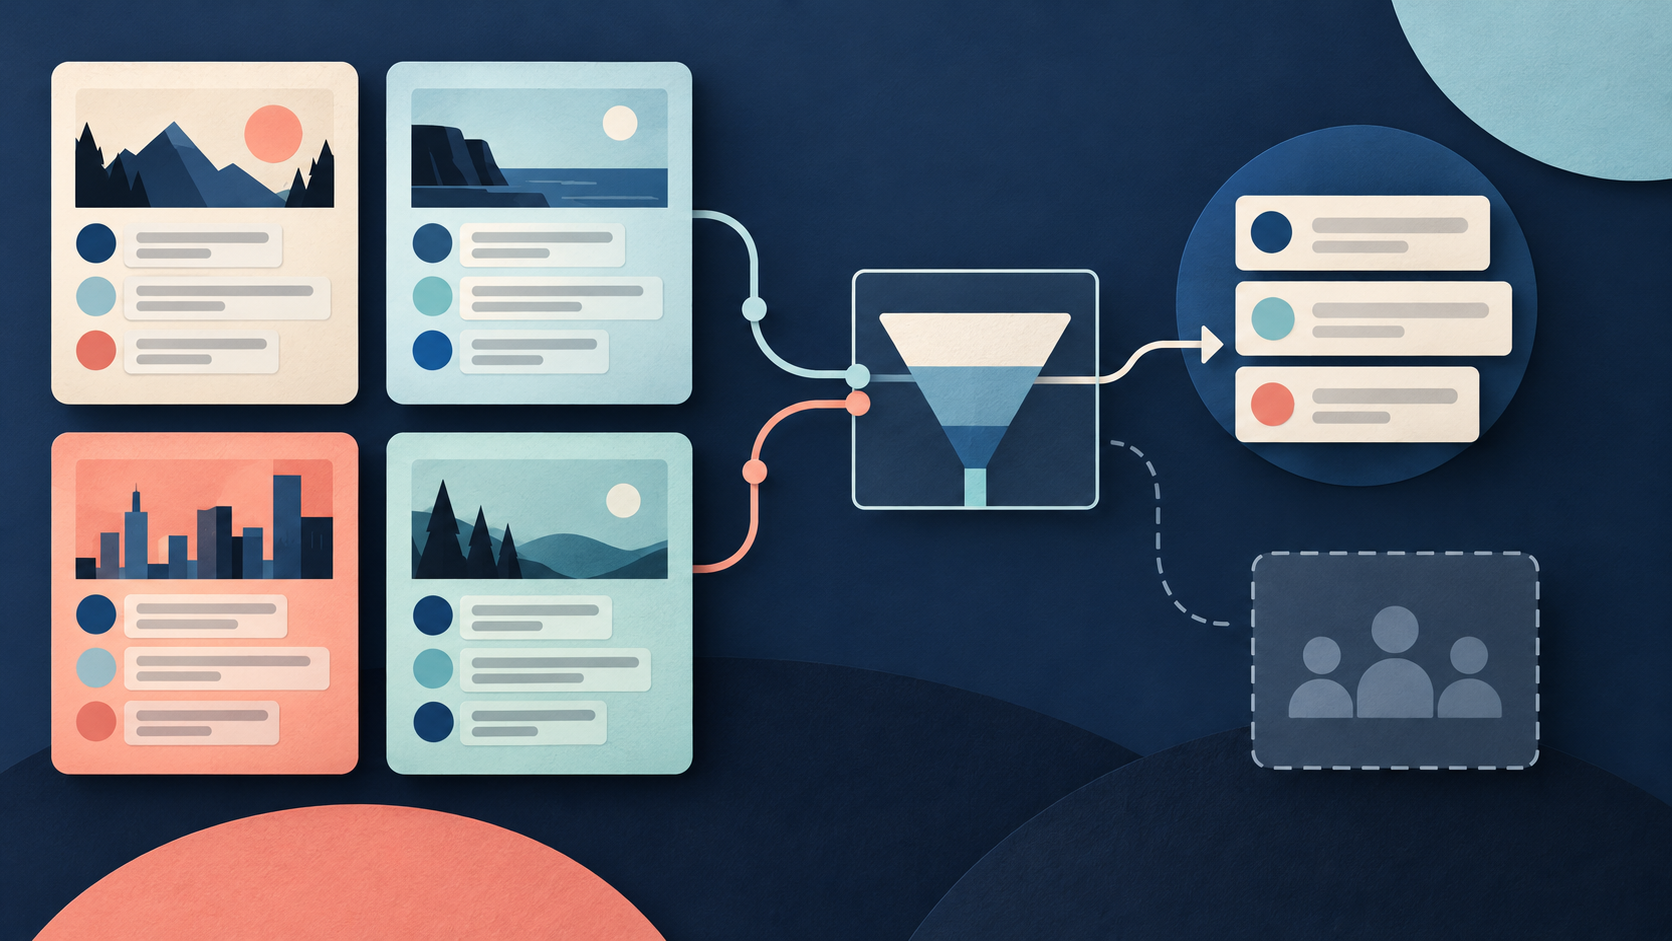
!Query cards connect to reviewed matches and separate noise and unknown trays.
Choose the records you need first
A keyword research job needs a clear output contract. This means a written statement of which records you need and what each record must explain.
For a focused study, that statement might be: collect posts for one query across two named communities, retain their source details, and review their meaning. You need to know which community you requested, where each post actually appeared, and which searches returned incomplete results.
A broader collection job needs different record types. Trudax documents posts, comments, communities, and users, alongside subreddit search, sorting, and date filters. That broader scope is the main reason to choose it for a combined collection job. Trudax documentation.
| Your required work | Recommended choice | Reason for this choice |
|---|---|---|
| Review unique post matches across named communities | Chronometrica | Requested and matched subreddit fields, query context, and separate search outcomes |
| Combine post search with community or user details, or known-thread comments | Trudax Reddit Scraper Lite | Broader documented collection modes |
Sources: Chronometrica, Trudax.
Write the required record types before you configure either tool. A list of posts cannot answer a question that requires the comments below each post. A large collection is also unnecessary when the decision needs a small set of reviewed examples.
This article helps you choose the collector and define its output. For a method to improve query relevance, use How to Track Reddit Keywords With Less Noise.
What Chronometrica makes explicit
Chronometrica documents five search settings: `query`, optional `subreddits`, `maxResults`, `sort`, and `time`. When you supply named subreddits, the input accepts between 1 and 20. This small set of settings fits a focused post-search job. Chronometrica documentation.
Its returned rows retain `inputQuery`, `requestedSubreddit`, `matchedSubreddit`, `canonicalPostUrl`, `postId`, and availability fields. Its `OUTPUT` also separates search outcomes, including empty, partial, and failed states. These details let you check the source of each saved post and the state of each search. Chronometrica documentation.
The requested community and the matched community answer different questions. `requestedSubreddit` records the community used for the search. `matchedSubreddit` records the community associated with the returned match. Compare them during review. If a record needs further checking, keep that question visible until you resolve it.
The query context matters when you later compare results from different searches. A post that appears in more than one research collection still needs a clear link to the search that found it. Retain the supplied `inputQuery` instead of relying on a filename or your memory.
Use `postId` to identify a post in your research records. Keep `canonicalPostUrl` so a reviewer can return to its source. Availability information helps you record whether the source can be checked. If a value is missing or unavailable, preserve that state. Do not replace it with zero.
These fields support a checked source panel: the set of communities and search settings you chose for the study. They do not establish that a post is relevant. That decision still requires reading the post against your research question.
Understand the total cap before you run
A cap is the maximum number of records a run can save. Chronometrica’s `maxResults` is a total cap on unique saved posts across the run. It is not a separate allowance for each subreddit. The checked schema permits values from 1 through 10,000. Chronometrica documentation and schema.
With two named subreddits and `maxResults` set to `12`, plan for at most 12 unique saved posts in total. Do not plan for 24. Do not assume that each community will supply six posts.
This distinction affects the research design. A total cap can suit a first review of relevant examples. It cannot guarantee equal sample sizes across communities. If equal counts are necessary, define that requirement before collection and check whether your collection plan can meet it.
If your requirement is every matching post and the expected result exceeds 10,000 unique posts in one run, Chronometrica does not meet that single-run requirement. It also does not promise complete Reddit coverage. Reaching the cap is a reason to treat the saved posts as a capped sample, not as all available evidence. Chronometrica documentation.
A smaller result is not proof that no other relevant posts exist. Search outcomes, source availability, the chosen query, and your community list all affect what you can conclude.
Start with a small, checked input
The public Search Posts in Subreddits Task provides a starting preset. A Task is a saved input preset. Inspect its input before running it; the existence of the public page does not verify its current saved settings.
This example uses the checked field names and values:
{
  "query": "open source AI",
  "subreddits": [
    "LocalLLaMA",
    "MachineLearning"
  ],
  "maxResults": 12,
  "sort": "new",
  "time": "month"
}The supplied input passed a check against the captured public JSON Schema. A JSON Schema defines allowed input fields and values. That check confirms the input’s structure. It does not prove that a live search will return posts. No collection run was made for this comparison. Chronometrica input schema.
Replace the query and community names with your intended public sources. Choose supported time and sort settings that match the study. Record them before collection so another reviewer can understand which search you intended to make.
For example, a review of recent discussion needs a defined period. A review of useful examples needs a written relevance rule. Those choices belong in the research plan, even when the collection input is small.
A fictional example: 12 saved posts, 9 accepted posts
The following example is fictional. It is not an Actor test, a live dataset, or a measured customer result.
An analyst studies discussion of open source AI in two named subreddits. The analyst sets a total cap of 12 unique posts. For this study, a relevant post must discuss a practical choice about using an open source AI model. A passing mention of the phrase does not qualify.
The fictional search saves seven unique posts from one community and five from the other:
`7 + 5 = 12 unique saved posts`
The analyst checks `requestedSubreddit` against `matchedSubreddit` and retains each `postId`. The analyst then reads all 12 posts. Three contain the search phrase but do not address the study’s question. Nine qualify:
`12 saved posts − 3 irrelevant posts = 9 accepted posts`
All 12 can be valid search results while only nine become useful evidence. Collection success and research relevance are separate checks.
The example also shows why a total cap needs careful reading. The cap was 12 across both communities. It was not `12 × 2 = 24`. The seven-to-five split does not prove that one community discusses the topic more often. It describes only the saved sample.
The analyst can use the nine accepted posts to study the questions and concerns they contain. The analyst cannot use this small keyword sample alone to estimate how common those concerns are across Reddit.
Use a five-step acceptance method
1. Define the question and the source panel
Name the keyword, subreddits, intended time setting, and sort setting. Then write one sentence that defines a relevant post.
A useful relevance rule identifies the subject and the evidence needed. “Contains our keyword” is a collection rule. “Describes a practical problem with the product category” is closer to a research rule. Choose the rule that serves your decision.
Keep a search-control table in your own research notes. Record the query, requested communities, intended settings, total cap, and collection date. This table explains what you asked the collector to do. It also prevents later readers from treating an undefined search as a complete study.
2. Select the collection mode
Use the required record types to make the product choice. For a focused post-search dataset, Chronometrica’s documented fields and search outcomes fit the acceptance method. Chronometrica documentation.
For Trudax search mode, clear `startUrls` or use an intentional search URL. Its README says `startUrls` take precedence over search settings. Trudax documentation.
Check the actual input before starting. A suitable product can still return an unsuitable collection if the input does not express your intended job.
3. Set the cap and retain unique observations
Choose a total saved-post cap that you can review. A first collection should be small enough to expose unclear relevance rules before you collect a larger sample.
Keep one research observation per unique post. Retain the post identifier, source URL, query context, and community fields. Keep your review notes separate from the collected text so readers can distinguish source content from your judgment.
Do not assume equal row counts across communities. If a comparison needs balanced groups, make balance an explicit acceptance condition. Check it after collection before comparing the groups.
4. Check outcomes and source details
Read the per-search outcomes as well as the post rows. An empty search, a partial search, and a failed search require different treatment. Chronometrica documents those states separately. Chronometrica documentation.
An empty result reports what that search returned. It does not prove there is no discussion of the topic. A partial result needs a visible limit on the conclusion. A failed search remains unresolved until you can assess or repeat it.
Compare requested and matched communities, inspect post identifiers, and retain availability information. Keep unresolved searches in the search-control table. Removing them would make the completed collection appear broader than the evidence supports.
5. Read each post and record a decision
Use a small acceptance code in your own notes. For example, use `accept`, `reject`, and `unknown`. These are suggested analyst labels, not claims about Actor output fields.
Accept a post when its content meets your relevance rule. Reject it when it clearly fails that rule. Use `unknown` when missing content or unclear meaning prevents a decision. Add a short reason so another person can check your judgment.
Report saved posts, accepted posts, rejected posts, and unresolved posts separately. Count zero only when you have checked that the count is zero. Keep missing or unknown values visible.
This method produces a reviewable sample. It does not turn search snippets or returned posts into a measure of prevalence across Reddit. For more help setting the study boundary, see Reddit customer research scope.
Add monitoring only after the sample is useful
A keyword collection becomes monitoring when you repeat it over time and act on changes. This comparison does not establish automatic alert delivery. If you need notifications, add separate scheduling and delivery steps.
First confirm that the query produces useful posts. Then choose how often to collect, how to identify posts already reviewed, and who will receive accepted results. Retaining `postId` gives your process a post identifier to check against earlier observations. Your monitoring process must perform that check.
Keep collection outcomes with each scheduled search. Otherwise, a failed search could look like a quiet period. Keep unknown results visible for the same reason.
Set a review rule for alerts too. A keyword mention may deserve review without deserving an immediate notification. The right threshold depends on the action the recipient can take. Test that decision on a small reviewed sample before you increase collection volume.
Sources & further reading
By Chronometrica · Updated
Back to top ↑